Data Center Cooling

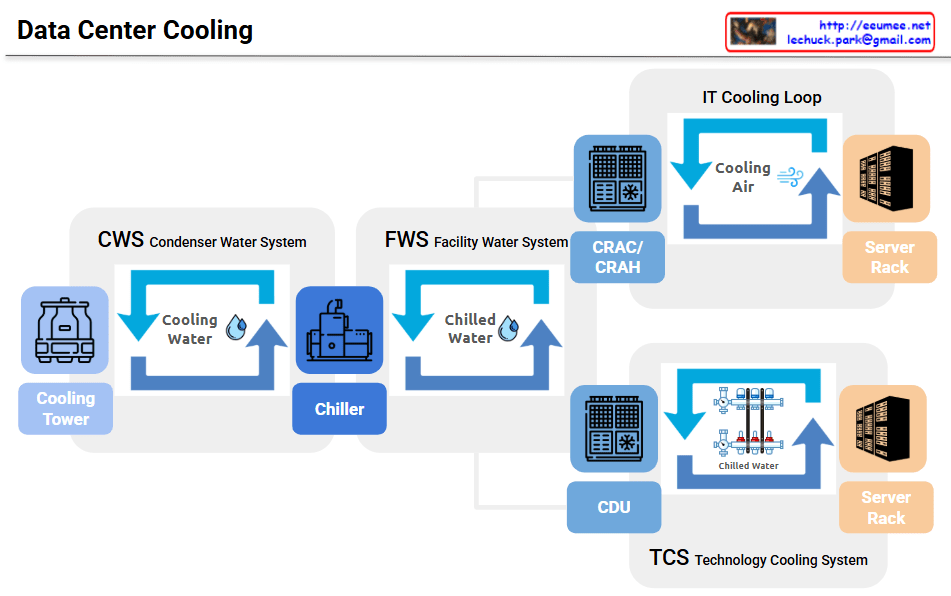
This diagram illustrates a hybrid Data Center Cooling Architecture, depicting how a facility manages thermal loads by combining traditional air cooling with advanced liquid cooling. The system is designed to support both standard infrastructure and high-density compute environments (such as AI clusters) simultaneously.

1. Facility-Level Thermal Management (Primary Infrastructure)

The left and center sections of the diagram represent the foundational facility water loops that capture and reject heat from the entire data center.

  • CWS (Condenser Water System): This is the heat rejection loop on the far left. Cooling Water circulates between the Chiller and the external Cooling Tower. The heat absorbed by the chiller from the facility’s interior is transferred to this loop and evaporated into the atmosphere via the cooling tower.
  • Chiller: Acts as the central refrigeration unit. It sits between the CWS and FWS, performing the critical energy transfer that cools the facility’s internal water supply.
  • FWS (Facility Water System): This is the internal primary loop. It circulates Chilled Water produced by the chiller throughout the building. As shown by the split branching lines on the right, this single FWS loop serves as the shared cold utility source for both cooling methodologies.

2. Dual-Path IT Heat Dissipation (Secondary Loops)

The FWS branches into two distinct pathways to accommodate different server densities and infrastructure types:

A. Air Cooling Pathway (Top Right)

  • Components: CRAC/CRAH (Computer Room Air Conditioner / Computer Room Air Handling unit) & IT Cooling Loop.
  • Mechanism: Chilled water from the FWS flows into the CRAC/CRAH units. Fans blow air over the chilled coils, generating Cooling Air. This cold air is forced through the data hall into the Server Rack to dissipate heat via convection.
  • Application: Ideal for traditional, low-to-medium density workloads.

B. Liquid Cooling Pathway (Bottom Right)

  • Components: CDU (Coolant Distribution Unit) & TCS (Technology Cooling System).
  • Mechanism: Chilled water from the FWS enters the CDU, which contains an internal heat exchanger. Rather than mixing the waters, the CDU uses the facility’s chilled water to cool a isolated, highly-purified secondary loop (TCS). The TCS then pumps this Chilled Water/Coolant directly through specialized manifolds and fluid conduits into the liquid-cooled Server Rack (e.g., via direct-to-chip cold plates).
  • Application: Critical for high-density deployments, such as GPU-accelerated AI servers, where air cooling alone is insufficient.

Summary

The diagram demonstrates a highly efficient, modern Hybrid Data Center Cooling Architecture. By leveraging a centralized primary chilling system (CWS & FWS), the facility successfully bifurcates its cooling delivery: utilizing traditional air cooling (CRAC/CRAH) for standard infrastructure while concurrently deploying precise, high-efficiency liquid cooling (CDU & TCS) to sustain high-density AI server racks.

#DataCenter #AIInfrastructure #LiquidCooling #TCS #CDU #ChilledWaterSystem #AIDC #MechanicalEngineering #ThermalManagement
The Paradigm Shift: From Brute Force to Efficiency

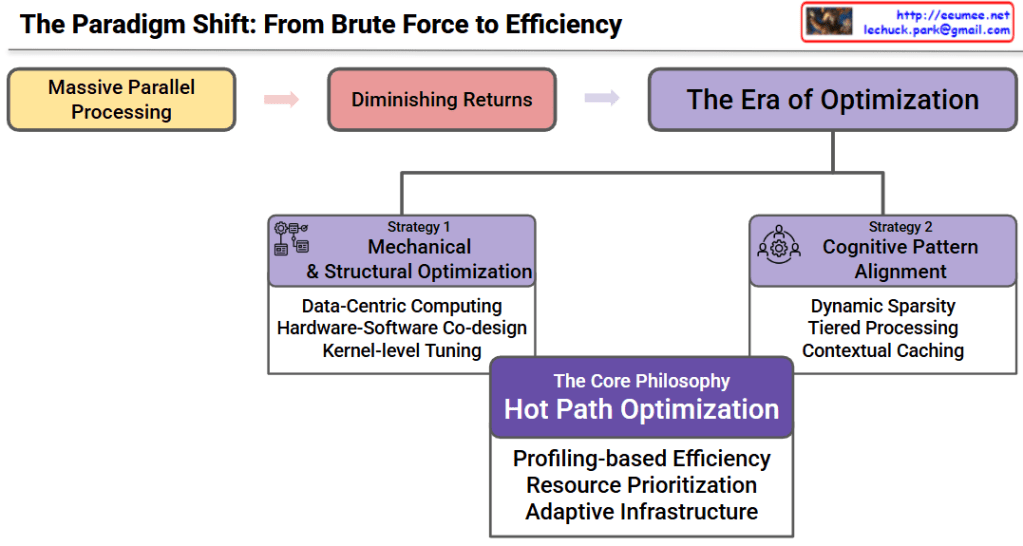
This diagram illustrates the critical paradigm shift currently happening in AI development: the transition from a “brute-force” approach—heavily reliant on massive infrastructure scaling and immense energy consumption—to a highly targeted, efficiency-first optimization perspective.

1. The Evolutionary Path in AI Infrastructure

The top flow outlines the historical and current trajectory of AI computing:

  • Massive Parallel Processing: This represents the “Brute Force” era of AI. Progress was historically driven by simply throwing massive GPU clusters and enormous amounts of electrical power at models to achieve scale.
  • Diminishing Returns: We are hitting a physical and energetic wall. Pumping more hardware and megawatts of power into data centers is yielding progressively smaller performance gains due to power density limits, cooling challenges, and silicon constraints.
  • The Era of Optimization: The new frontier of AI development. Since we can no longer rely purely on adding more servers and power, the focus has entirely shifted to extracting maximum compute-per-watt and maximizing the utilization of existing infrastructure.

2. The Dual-Pillar Strategy for Efficiency

To navigate away from energy-heavy brute force, the diagram proposes two distinct but complementary optimization approaches:

Strategy 1: Mechanical & Structural Optimization

This focuses on the physical and foundational software layers to prevent energy and computational waste.

  • Data-Centric Computing: Keeping data close to the processing units to reduce the massive energy cost of moving data across networks.
  • Hardware-Software Co-design: Building AI software that is perfectly aligned with the underlying silicon to maximize throughput without drawing excess power.
  • Kernel-level Tuning: Fine-tuning the operating system at the lowest level to remove overhead and latency.

Strategy 2: Cognitive Pattern Alignment

This focuses on algorithmic and logical efficiency, ensuring the AI models themselves are running “smarter.”

  • Dynamic Sparsity: Skipping unnecessary calculations in AI models (like ignoring zero-values in neural networks), drastically reducing the required compute power.
  • Tiered Processing: Assigning tasks to the right level of hardware based on complexity, so high-power GPUs are only used when absolutely necessary.
  • Contextual Caching: Intelligently predicting and storing data to speed up AI inference without repeatedly fetching it from main memory.

3. The Core Philosophy: Hot Path Optimization

At the foundation of this new era is Hot Path Optimization, the ultimate answer to the energy and infrastructure bottleneck.

Instead of keeping the entire AI data center running at maximum power, this philosophy dictates:

  • Profiling-based Efficiency: Identifying the exact “Hot Paths” (the most frequent and critical computational bottlenecks in the AI workload).
  • Resource Prioritization: Funneling the best hardware and power strictly into those critical paths, rather than wasting energy on idle or low-priority tasks.
  • Adaptive Infrastructure: Creating an environment that dynamically scales power and resources in real-time to match the exact needs of the AI model, achieving peak efficiency.

#AIInfrastructure #EnergyEfficiency #SustainableAI #OptimizationEra #GreenDataCenter #HotPathOptimization #ComputePerWatt #TechVisualization

2 GPU Throttling

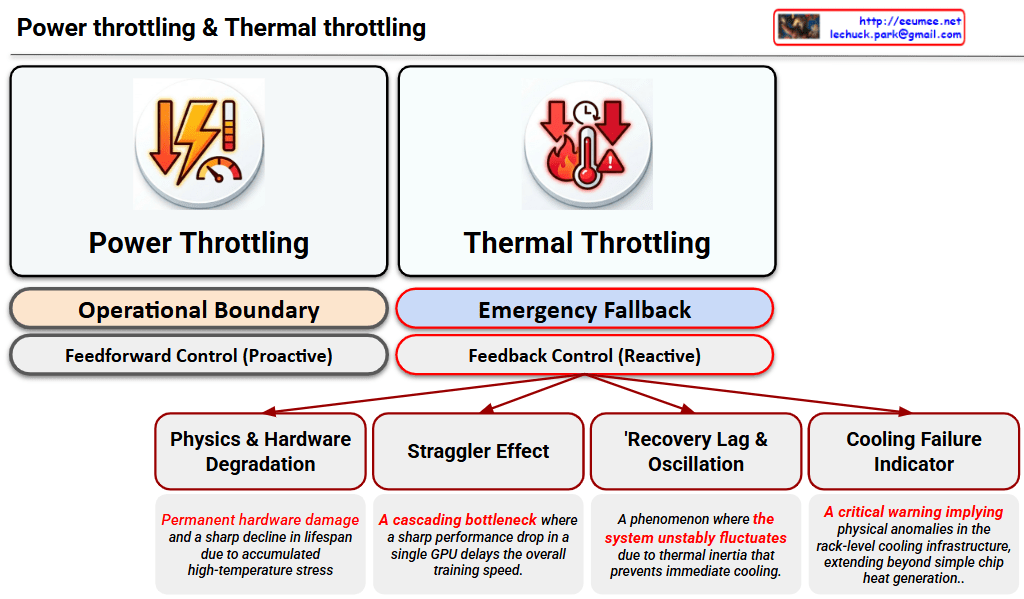
This image is a Visual Engineering diagram that contrasts the fundamental control mechanisms of Power Throttling and Thermal Throttling at a glance, specifically highlighting the critical impact thermal throttling has on the system.


1. Philosophical and Structural Contrast (Top Section)

The diagram places the two throttling methods side-by-side, clearly distinguishing them not just as similar performance limiters, but as mechanisms with completely different operational philosophies.

  • Left: Power Throttling
    • Operational Boundary: Indicates that this acts as a safety line, keeping the system operating ‘normally’ within its designed power limits.
    • Feedforward Control (Proactive): Specifies that this is a proactive control method that restricts input (power demand) before a negative result occurs, fundamentally preventing the issue from happening.
  • Right: Thermal Throttling
    • Emergency Fallback: Shows that this is not a normal operational state, but a ‘last line of defense’ triggered to prevent physical destruction.
    • Feedback Control (Reactive): Emphasizes that this is a reactive control method that drops clock speeds only after detecting the result (high heat exceeding the safe threshold).

2. Four Fatal Risks of Thermal Throttling (Bottom Tree Structure)

The core strength of the diagram lies in placing the sub-tree structure exclusively under Thermal Throttling. This highlights that this phenomenon goes beyond a simple performance drop, breaking down its complex, detrimental impacts on the infrastructure into four key factors:

  1. Physics & Hardware Degradation: Refers to direct damage to semiconductors (silicon) and the shortening of their lifespan (MTBF) due to the accumulated stress of high heat.
  2. Straggler Effect: Points out the bottleneck phenomenon in environments like distributed AI training. A delay in a single, thermally throttled node drags down the synchronization and data processing speed of the entire cluster.
  3. Thermal Inertia & Thermal Oscillations: Describes the unstable fluctuation of system performance. Because heat does not dissipate instantly (thermal inertia), the system repeatedly drops and recovers clock speeds, causing the performance to oscillate.
  4. Cooling Failure Indicator: Acts as a severe alarm. It implies that the issue extends beyond a hot chip—it indicates that the facility’s infrastructure, such as the rack-level Direct Liquid Cooling (DLC) capacity, has reached its physical limit or experienced an anomaly.

Overall Summary:

The diagram logically and intuitively delivers a powerful core message: “Power Throttling is a normal, proactive control within predictable bounds, whereas Thermal Throttling is a severe, reactive warning at both the hardware and infrastructure levels after control is lost.” It is an excellent piece of work that elegantly structures complex system operations using concise text and layout.

#DataCenter #AIInfrastructure #GPUCooling #ThermalThrottling #PowerThrottling #HardwareEngineering #HighPerformanceComputing #LiquidCooling #SystemArchitecture

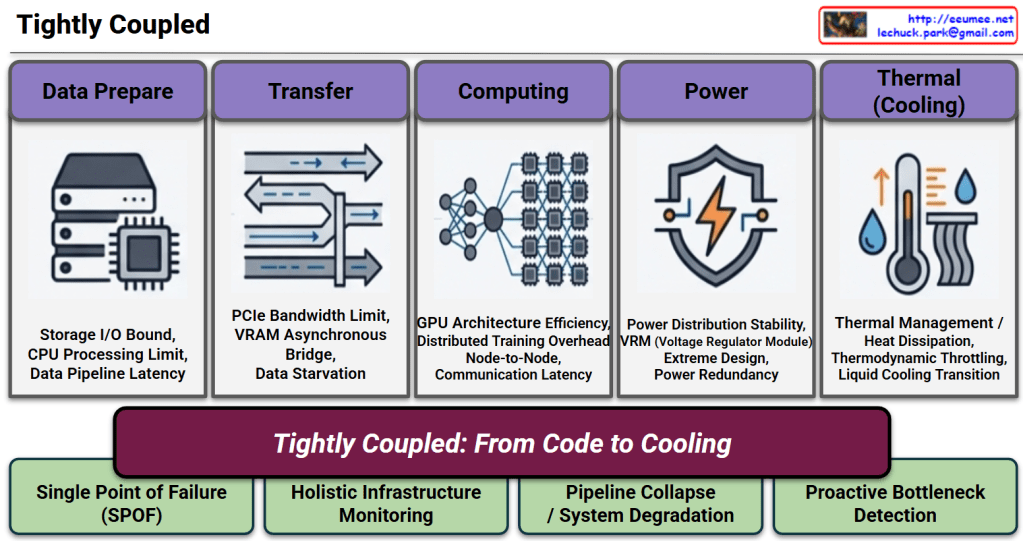
Tightly Coupled AI Works

📊A Tightly Coupled AI Architecture

1. The 5 Pillars & Potential Bottlenecks (Top Section)

  • The Flow: The diagram visualizes the critical path of an AI workload, moving sequentially through Data Prepare ➔ Transfer ➔ Computing ➔ Power ➔ Thermal (Cooling).
  • The Risks: Below each pillar, specific technical bottlenecks are listed (e.g., Storage I/O Bound, PCIe Bandwidth Limit, Thermodynamic Throttling). This highlights that each stage is highly sensitive; a delay or failure in any single component can starve the GPU or cause system-wide degradation.

2. The Core Message (Center Section)

  • The Banner: The central phrase, “Tightly Coupled: From Code to Cooling”, acts as the heart of the presentation. It boldly declares that AI infrastructure is no longer divided into “IT” and “Facilities.” Instead, it is a single, inextricably linked ecosystem where the execution of a single line of code directly translates to immediate physical power and cooling demands.

3. Strategic Implications & Solutions (Bottom Section)

  • The Reality (Left): Because the system is so interdependent, any Single Point of Failure (SPOF) will lead to a complete Pipeline Collapse / System Degradation.
  • The Operational Shift (Right): To prevent this, traditional siloed management must be replaced. The slide strongly argues for Holistic Infrastructure Monitoring and Proactive Bottleneck Detection. It visually proves that reacting to issues after they happen is too late; operations must be predictive and unified across the entire stack.

💡Summary

  • Interdependence: AI data centers operate as a single, highly sensitive organism where one isolated bottleneck can collapse the entire computational pipeline.
  • Paradigm Shift: The tight coupling of software workloads and physical facilities (“From Code to Cooling”) makes legacy, reactive monitoring obsolete.
  • Strategic Imperative: To ensure stability and efficiency, operations must transition to holistic, proactive detection driven by intelligent, autonomous management solutions.

#AIDataCenter #TightlyCoupled #InfrastructureMonitoring #ProactiveOperations #DataCenterArchitecture #AIInfrastructure #Power #Computing #Cooling #Data #IO #Memory


With Gemini

Legacy vs AI DC

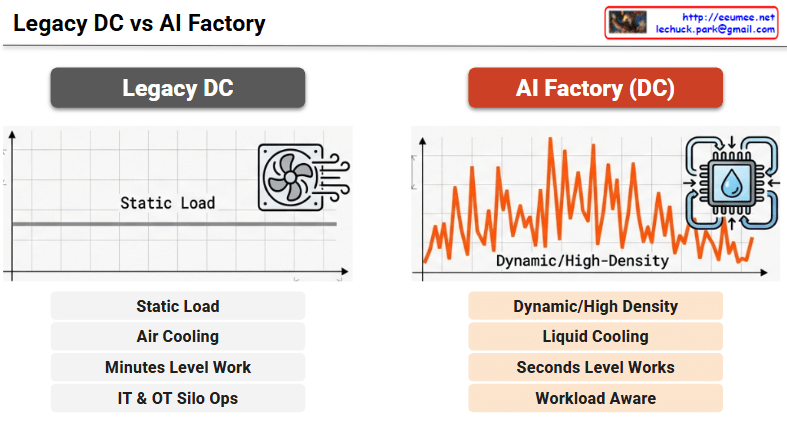
Legacy DC vs. AI Factory

1. Legacy Data Center

  • Static Load: The flat line on the graph indicates that power and compute demands are stable, continuous, and highly predictable.
  • Air Cooling: Traditional fan-based air cooling systems are sufficient to manage the heat generated by standard, lower-density server racks.
  • Minutes Level Work: System responses, resource provisioning, and facility adjustments generally occur on a scale of minutes.
  • IT & OT Silo Ops: Information Technology (servers, networking) and Operational Technology (power, cooling facilities) are managed independently in isolated silos, with no real-time data exchange.

2. AI Factory (DC)

  • Dynamic/High-Density: The volatile, jagged graph illustrates how AI workloads create extreme, rapid power spikes and demand highly dense computing resources.
  • Liquid Cooling: The immense heat output from high-performance AI chips necessitates advanced liquid cooling solutions (represented by the water drop and circulation arrows) to maintain thermal efficiency.
  • Seconds Level Works: The physical infrastructure must be highly agile, detecting and responding to sudden dynamic workload changes and thermal shifts within seconds.
  • Workload Aware: The facility dynamically adapts its cooling and power based on real-time AI computing needs. Establishing this requires robust “IT/OT Data Convergence” and the utilization of “High-Fidelity Data” as key components of a broader “Digitalization” strategy.

Summary

  1. Legacy data centers are designed for predictable, static loads using traditional air cooling, with IT and facility operations (OT) isolated from one another.
  2. AI Factories must handle highly volatile, high-density workloads, making liquid cooling and instantaneous, seconds-level infrastructure responses mandatory.
  3. Transitioning to a true “Workload Aware” facility requires a strong “Digitalization” strategy centered around “IT/OT Data Convergence” and “High-Fidelity Data.”

#AIFactory #DataCenter #LiquidCooling #WorkloadAware #ITOTConvergence #HighFidelityData #Digitalization #AIInfrastructure

With Gemini

Prefill & Decode

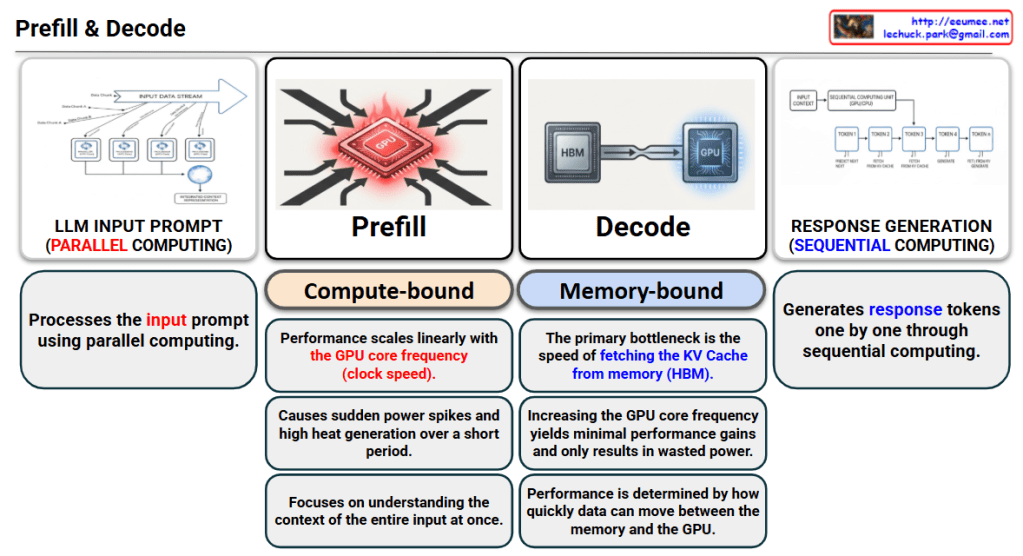
This image illustrates the dual nature of Large Language Model (LLM) inference, breaking it down into two fundamental stages: Prefill and Decode.


1. Prefill Stage: Input Processing

The Prefill stage is responsible for processing the initial input prompt provided by the user.

  • Operation: It utilizes Parallel Computing to process the entire input data stream simultaneously.
  • Constraint: This stage is Compute-bound.
  • Performance Drivers:
    • Performance scales linearly with the GPU core frequency (clock speed).
    • It triggers sudden power spikes and high heat generation due to intensive processing over a short duration.
    • The primary goal is to understand the context of the entire input at once.

2. Decode Stage: Response Generation

The Decode stage handles the actual generation of the response, producing one token at a time.

  • Operation: it utilizes Sequential Computing, where each new token depends on the previous ones.
  • Constraint: This stage is Memory-bound (specifically, memory bandwidth-bound).
  • Performance Drivers:
    • The main bottleneck is the speed of fetching the KV Cache from memory (HBM).
    • Increasing the GPU clock speed provides minimal performance gains and often results in wasted power.
    • Overall performance is determined by the data transfer speed between the memory and the GPU.

Summary

  1. Prefill is the “understanding” phase that processes prompts in parallel and is limited by GPU raw computing power (Compute-bound).
  2. Decode is the “writing” phase that generates tokens one by one and is limited by how fast data moves from memory (Memory-bound).
  3. Optimizing LLMs requires balancing high GPU clock speeds for input processing with high memory bandwidth for fast output generation.

#LLM #Inference #GPU #PrefillVsDecode #AIInfrastructure #DeepLearning #ComputeBound #MemoryBandwidth

With Gemini

AI DC Power Risk


Technical Analysis: AI Load & Weak Grid Interaction

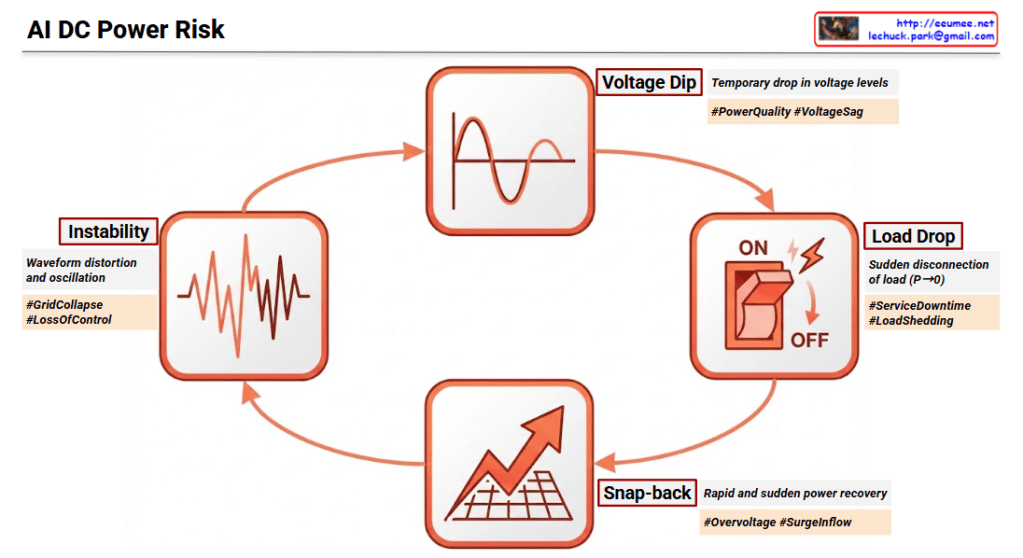
The integration of massive AI workloads into a Weak Grid (SCR:Short Circuit Ratio < 3) creates a high-risk environment where electrical Transients can escalate into systemic failures.

1. Voltage Dip (Transient Voltage Sag)

  • Mechanism: AI workloads are characterized by Step Power Changes and Pulse-type Profiles. When these massive loads activate simultaneously, they cause an immediate Transient Voltage Sag in a weak grid due to high impedance.
  • Impact: This compromises Power Quality, leading to potential malfunctions in voltage-sensitive AI hardware.

2. Load Drop (Transient Load Rejection)

  • Mechanism: If the voltage sag exceeds safety thresholds, protection systems trigger Load Rejection, causing the power consumption to plummet to zero (P -> 0).
  • Impact: This results in Service Downtime and creates a massive power imbalance in the grid, often referred to as Load Shedding.

3. Snap-back (Transient Recovery & Inrush)

  • Mechanism: As the grid attempts to recover or the load is re-engaged, it creates a Transient Recovery Voltage (TRV).
  • Impact: This phase often sees Overvoltage (Overshoot) and a massive Surge Inflow (Inrush Current), which places extreme electrical stress on power components and can damage sensitive circuitry.

4. Instability (Dynamic & Harmonic Oscillation)

  • Mechanism: The repetition of sags and surges leads to Dynamic Oscillation. The control systems of power converters may lose synchronization with the grid frequency.
  • Impact: The result is severe Waveform Distortion, Loss of Control, and eventually a total Grid Collapse (Blackout).

Key Insight (NERC 2025 Warning)

The North American Electric Reliability Corporation (NERC) warns that the reduction of voltage-sensitive loads and the rise of periodic, pulse-like AI workloads are primary drivers of modern grid instability.


Summary

  1. AI Load Dynamics: Rapid step-load changes in AI data centers act as a “shock” to weak grids, triggering a self-reinforcing cycle of electrical failure.
  2. Transient Progression: The cycle moves from a Voltage Sag to a Load Trip, followed by a damaging Power Surge, eventually leading to non-damped Oscillations.
  3. Strategic Necessity: To break this cycle, data centers must implement advanced solutions like Grid-forming Inverters or Fast-acting BESS to provide synthetic inertia and voltage support.

#PowerTransients #WeakGrid #AIDataCenter #GridStability #NERC2025 #VoltageSag #LoadShedding #ElectricalEngineering #AIInfrastructure #SmartGrid #PowerQuality

With Gemini