Autonomous Facility Operation Optimization Pipeline


Autonomous Facility Operation Optimization Pipeline

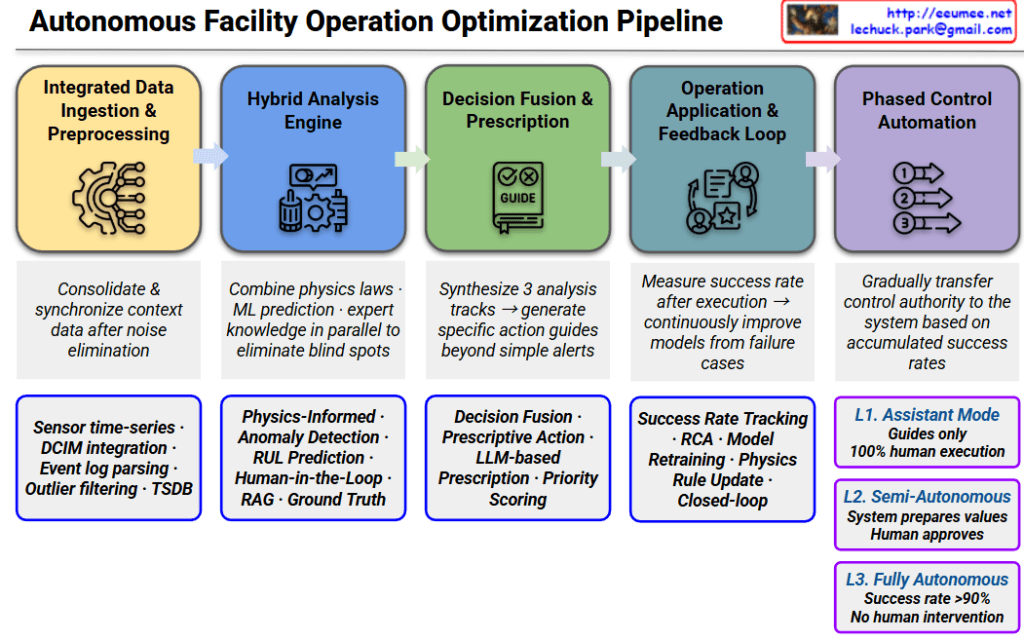
This pipeline represents a sophisticated 5-stage workflow designed to transition facility management from manual oversight to full AI-driven autonomy, ensuring reliability through hybrid modeling.

1. Integrated Data Ingestion & Preprocessing

  • Role: Consolidates diverse data streams into a synchronized, high-fidelity format by eliminating noise.
  • Key Components: Sensor time-series data, DCIM integration, Event log parsing, Outlier filtering, and TSDB (Time Series Database).

2. Hybrid Analysis Engine

  • Role: Eliminates analytical blind spots by running physical laws, machine learning predictions, and expert knowledge in parallel.
  • Key Components: Physics-Informed Machine Learning (PIML), Anomaly Detection, RUL (Remaining Useful Life) Prediction, and RAG-enhanced Ground Truth analysis.

3. Decision Fusion & Prescription

  • Role: Synthesizes multi-track analysis to move beyond simple alerts, generating specific, actionable “prescriptions.”
  • Key Components: Decision Fusion, Prescriptive Action, LLM-based Prescription, and Priority Scoring to rank urgency.

4. Operation Application & Feedback Loop

  • Role: Establishes a closed-loop system that measures success rates post-execution to continuously refine models.
  • Key Components: Success Rate Tracking, RCA (Root Cause Analysis), Model Retraining, and Physics/Rule updates based on real-world performance.

5. Phased Control Automation

  • Role: A risk-mitigated transition of control authority from humans to AI based on accumulated performance data.
  • Automation Levels:
    • L1. Assistant Mode: System provides guides only; 100% human execution.
    • L2. Semi-Autonomous: System prepares optimized values; human provides final approval.
    • L3. Fully Autonomous: System operates without human intervention (triggered when success rate >90%).

Strategic Insight

The hallmark of this architecture is the integration of Physics-Informed ML and LLM-based reasoning. By combining the rigid reliability of physical laws with the adaptive reasoning of Large Language Models, the pipeline solves the “black box” problem of traditional AI, making it suitable for mission-critical infrastructures like AI Data Centers.

#DataCenter #AIOps #AutonomousInfrastructure #PhysicsInformedML #DigitalTwin #LLM #PredictiveMaintenance #DataCenterOptimization #TechVisualization #SmartFacility #EngineeringExcellence
Event Roll-Up by LLM

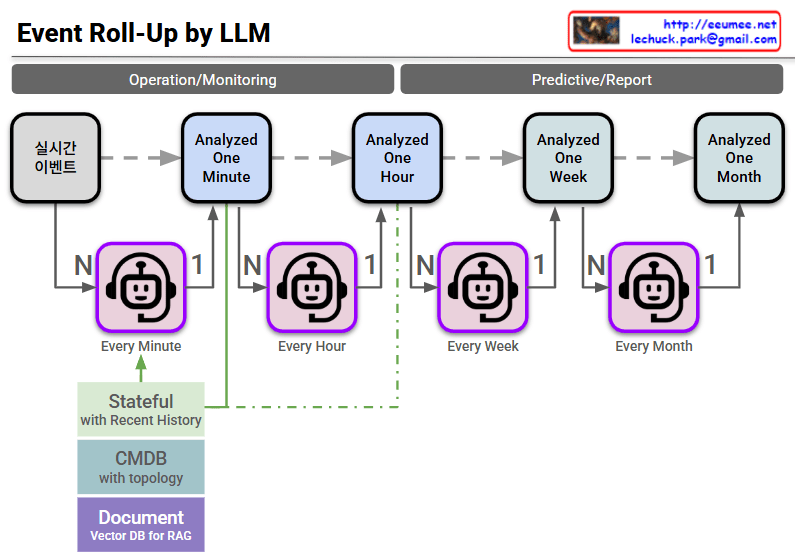
The provided image illustrates an AIOps-based event pipeline architecture. It demonstrates how Large Language Models (LLMs) hierarchically roll up and analyze the flood of real-time events occurring within a data center or large-scale IT infrastructure over time.

The core objective here is to compress countless simple alarms into meaningful insights, drastically reducing alert fatigue and minimizing Mean Time To Repair (MTTR). The architecture can be broken down into three main areas:

1. Separation by Purpose (Top Banner)

  • Operation/Monitoring: Encompasses the 1-minute and 1-hour analysis cycles. This zone is dedicated to immediate anomaly detection and real-time incident response.
  • Predictive/Report: Encompasses the 1-week and 1-month analysis cycles. By leveraging accumulated data, this zone focuses on identifying long-term failure trends, assisting with infrastructure capacity planning, and automatically generating weekly or monthly operational reports.

2. N:1 Hierarchical Roll-Up Mechanism (Center Pipeline)

The robot icons (LLM Agents) deployed at each time interval act as summarization engines, merging data from the lower tier and passing it up the chain.

  • Every Minute: The agent collects numerous real-time events (N) and compresses them into a summarized, 1-minute contextual block (1).
  • Every Hour / Week / Month: The agents aggregate multiple analytical outputs (N) from the preceding stage into a single, comprehensive analysis for the larger time window (1).
  • Through this mechanism, granular noise is progressively filtered out over time, leaving only the macroscopic health status and the most critical issues of the entire infrastructure.

3. Context & Knowledge Injection (Bottom Left)

For an LLM to go beyond simple text summarization and accurately assess the actual state of the infrastructure, it requires grounding. These elements provide that crucial context and are heavily injected during the initial (1-minute) analysis phase.

  • Stateful (with Recent History): Instead of treating events as isolated incidents, the system remembers recent context to track the continuity and transitions of system states.
  • CMDB (with topology): By integrating with the Configuration Management Database, the system understands the physical and logical relationships (e.g., power dependencies, network paths) between the alerting equipment and the rest of the infrastructure.
  • Document (Vector DB for RAG): This is a vectorized repository of operational manuals, past incident resolutions, and Standard Operating Procedures (SOPs). Utilizing Retrieval-Augmented Generation (RAG), it feeds specific domain knowledge to the LLM, enabling it to diagnose root causes and recommend highly accurate remediation steps.

In Summary:

This architecture represents a significant leap from traditional rule-based monitoring. It is a highly systematic blueprint designed to intelligently interpret real-time events by powering LLM agents with RAG and CMDB topology context. Ultimately, it paves the way for reducing manual operator intervention and achieving truly autonomous and proactive infrastructure management.


#AIOps #LLM #AgenticAI #RAG #EventRollUp #ITInfrastructure #AutonomousOperations #MTTR #Observability #TechArchitecture

Hybrid Analysis for Autonomous Operation (2)

Framework Overview

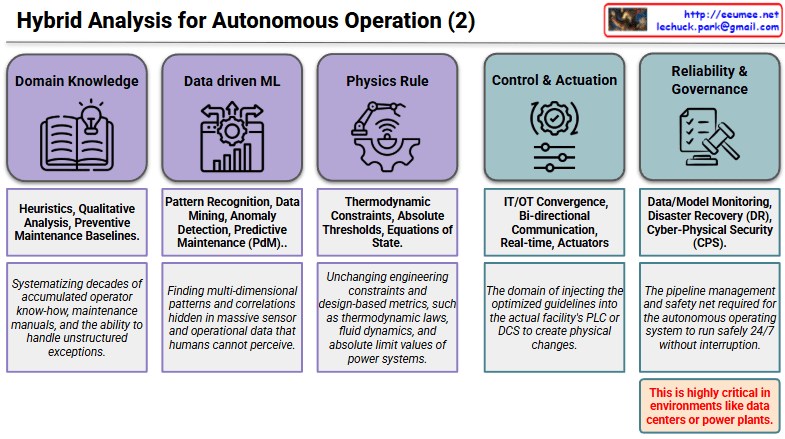
The image illustrates a “Hybrid Analysis” framework designed to achieve true Autonomous Operation. It outlines five core pillars required to build a reliable, self-driving system for high-stakes environments like AI data centers or power plants. The architecture combines three analytical foundations (purple) with two execution and safety layers (teal).


1. The Analytical Foundation (The Hybrid Triad)

This section forms the “brain” of the autonomous system, blending human expertise, artificial intelligence, and absolute scientific laws.

  • Domain Knowledge (Human Experience):
    • Core: Systematized heuristics, decades of operator know-how, and maintenance manuals.
    • Role: Provides qualitative analysis, establishes preventive maintenance baselines, and handles unstructured exceptions that algorithms might miss.
  • Data-driven ML (Artificial Intelligence):
    • Core: Pattern recognition, anomaly detection, and Predictive Maintenance (PdM).
    • Role: Analyzes massive volumes of multi-dimensional sensor and operational data to find hidden correlations and risks that are imperceptible to human operators.
  • Physics Rule (Engineering Guardrails):
    • Core: Thermodynamic constraints, equations of state, fluid dynamics, and absolute power limits.
    • Role: Acts as the ultimate boundary. It ensures that the operational commands generated by ML models are physically possible and safe, preventing the AI from violating unchanging engineering laws.

2. Execution and Safety Nets

This section translates the insights from the analytical triad into real-world, physical changes while guaranteeing system stability.

  • Control & Actuation (The Hands):
    • Core: IT/OT (Information Technology / Operational Technology) convergence and real-time bi-directional communication.
    • Role: The domain of injecting the optimized setpoints and guidelines directly into the facility’s PLC (Programmable Logic Controller) or DCS (Distributed Control System) to drive physical actuators.
  • Reliability & Governance (The Shield):
    • Core: Data/Model monitoring, Disaster Recovery (DR), and Cyber-Physical Security (CPS).
    • Role: The overarching safety net and pipeline management required to ensure the autonomous operating system runs securely and continuously, 24/7, without interruption.

💡 Key Takeaway

As emphasized by the red text at the bottom, this multi-layered approach is highly critical in environments like data centers or power plants. Relying solely on data-driven ML is too risky for high-density infrastructure; true autonomous stability is only achieved when AI is anchored by human domain expertise and strict physical laws.

#AutonomousOperations #AIOps #HybridAnalysis #PredictiveMaintenance #ITOTConvergence #CyberPhysicalSystems #MissionCritical #TechVisualization #EngineeringInfographic

With Gemini

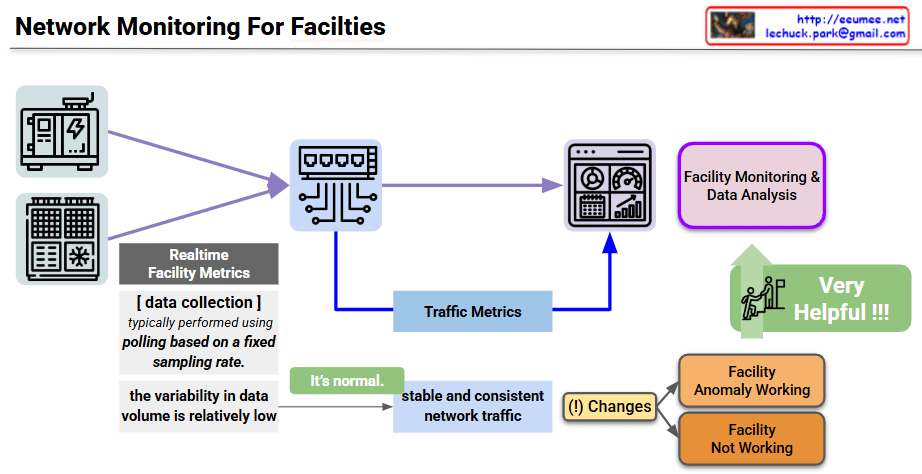
Network Monitoring For Facilities

The provided image is a conceptual diagram illustrating how to monitor the status and detect anomalies in critical industrial facility infrastructure (such as power and cooling) through network traffic patterns. I also noticed the author’s information (Lechuck) in the top right corner! Let’s break down the main data flow and core ideas of your diagram step-by-step.

1. Realtime Facility Metrics

  • Target: Physical facility equipment such as generators (power infrastructure) and HVAC/cooling units.
  • Collection Method: A central monitoring server primarily uses a Polling method, requesting and receiving status data from the equipment based on a fixed sampling rate.
  • Characteristics: Because a specific amount of data is exchanged at designated times, the variability in data volume during normal operation is relatively low.

2. Traffic Metrics (Inferring Status via Traffic Characteristics)

This section contains the core insight of the diagram. Beyond just analyzing the payload of the collected sensor data, the pattern of the network traffic itself is utilized as an indicator of the facility’s health.

  • Normal State (It’s normal): When the equipment is operating normally, the network traffic occurs in a very stable and consistent manner in sync with the polling cycle.
  • Detecting Traffic Changes ((!) Changes): If a change occurs in this expected stable traffic pattern (e.g., traffic spikes, response delays, or disconnections), it is flagged as an anomaly in the facility.
  • Status Classification: Based on these abnormal traffic patterns, the system can infer whether the equipment is operating abnormally (Facility Anomaly Working) or has completely stopped functioning (Facility Not Working).

3. Facility Monitoring & Data Analysis

  • This architecture combines standard dashboard monitoring with Traffic Metrics extracted from network switches, feeding them into the data analysis system.
  • This cross-validation approach is highly effective for distinguishing between actual sensor data errors and network segment failures. As highlighted in the diagram, this ultimately improves the overall reliability of the facility monitoring system (Very Helpful !!!).

💡 Summary

This architecture presents a highly intuitive and efficient approach to data center and facility operations. By leveraging the network engineering characteristic that facility equipment communicates in regular patterns, it demonstrates an excellent monitoring logic. It allows operators to perform initial fault detection almost immediately simply by observing “changes in the consistency of network traffic,” even before conducting complex sensor data analysis.

#NetworkMonitoring #DataCenterOperations #FacilityManagement #TrafficAnalysis #AnomalyDetection #NetworkEngineering #ITInfrastructure #AIOps #SmartFacilities

With Gemini

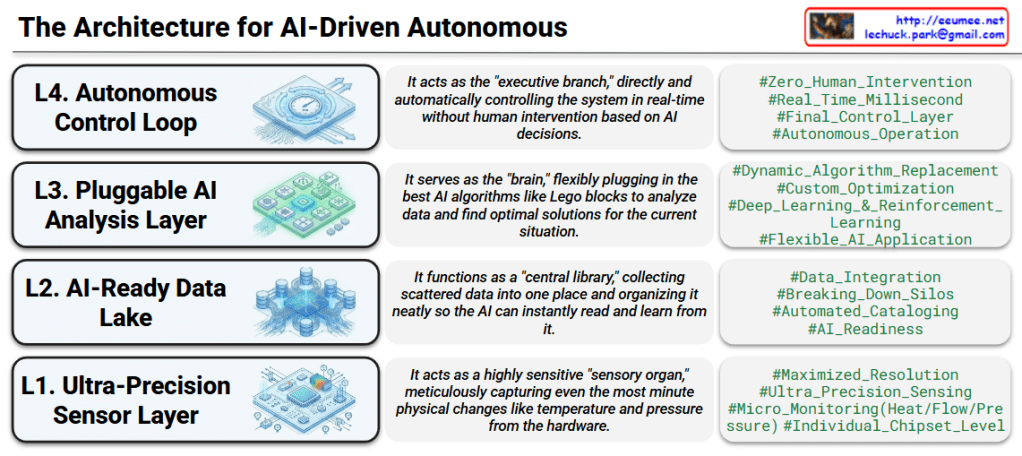
The Architecture for AI-Driven Autonomous

This slide effectively illustrates a complete, four-tier architecture required to build a fully autonomous AI system. Let’s walk through the framework from the foundation (data collection) to the top (autonomous execution):

  • L1. Ultra-Precision Sensor Layer (The “Sensory Organ”)This foundational layer is all about high-resolution data capture. Acting as the system’s highly sensitive sensory organs, it meticulously monitors minute physical changes—such as heat, flow, and pressure—right down to the individual chipset level.
  • L2. AI-Ready Data Lake (The “Central Library”)Once the data is captured, it flows into this layer to be consolidated. It breaks down data silos by collecting scattered facility data into one centralized library. It then automatically catalogs this information so that the AI can instantly access, read, and learn from it.
  • L3. Pluggable AI Analysis Layer (The “Brain”)This is where the cognitive processing happens. Acting as the brain of the system, it analyzes the organized data to find optimal solutions. Its “pluggable” nature means you can dynamically swap in the best AI algorithms—like Deep Learning or Reinforcement Learning—just like snapping Lego blocks together to fit the specific situation.
  • L4. Autonomous Control Loop (The “Executive Branch”)Finally, the insights from the brain are turned into action here. This layer operates in real-time (down to the millisecond) to send control signals back to the system. It executes decisions entirely on its own, achieving true autonomous operation with zero human intervention.

Summary

This architecture demonstrates a seamless, end-to-end operational flow: it starts by sensing microscopic hardware changes (L1), structures that raw data for immediate AI consumption (L2), applies dynamic and flexible algorithms to make smart decisions (L3), and ultimately executes those decisions autonomously in real-time (L4). It is a perfect blueprint for achieving a fully uncrewed, intelligent infrastructure.

#AIArchitecture #AutonomousSystems #EdgeComputing #DataLake #AIOps #SmartInfrastructure #MachineLearning #Automation

With Gemini

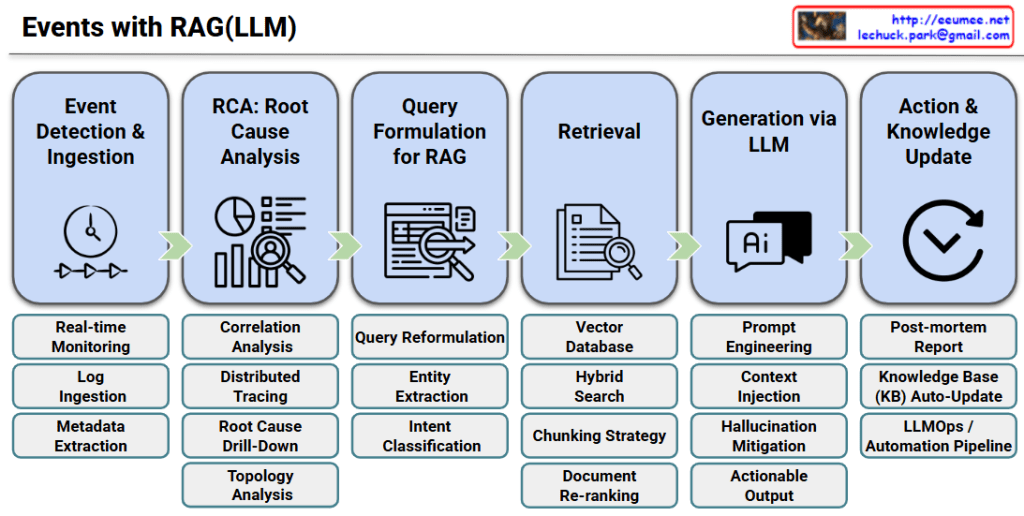
Events with RAG(LLM)

Step 1: Event Detection & Ingestion

This initial stage focuses on capturing system anomalies through real-time monitoring, collecting necessary logs, and extracting essential metadata to understand the context of the event.

Step 2: RCA: Root Cause Analysis

It identifies the fundamental issue behind the surface-level symptoms by utilizing correlation analysis, distributed tracing, root cause drill-down, and infrastructure topology analysis.

Step 3: Query Formulation for RAG

The system translates the RCA findings into an optimized search prompt through query reformulation, entity extraction, and intent classification to fetch the most accurate solutions.

Step 4: Retrieval

It searches for the most relevant technical documents or past incident records from a Vector Database, leveraging hybrid search, chunking strategies, and document re-ranking techniques.

Step 5: Generation via LLM

The LLM generates an actionable troubleshooting guide by combining prompt engineering and context injection, strictly mitigating any AI hallucinations.

Step 6: Action & Knowledge Update

Finally, after the issue is resolved, the system automatically updates its knowledge base with post-mortem reports, ensuring a continuous feedback loop through an automated LLMOps pipeline.


Summary

  1. Event Detection & Root Cause Analysis: When a system incident occurs, it is captured in real-time, and the system deeply traces the actual root cause rather than just addressing surface-level symptoms.
  2. Knowledge Retrieval & Solution Generation: The analyzed root cause is transformed into a RAG-optimized query to retrieve the best reference documents from the internal knowledge base, allowing the LLM to generate an immediately actionable troubleshooting guide.
  3. Knowledge Capitalization & Virtuous Cycle: Once the issue is resolved, a post-mortem report is generated and automatically fed back into the knowledge base, creating a continuously evolving and automated pipeline.

#AIOps #RAG_Architecture #RootCauseAnalysis #LLMOps #IncidentManagement #TroubleshootingAutomation #VectorDatabase

With Gemini

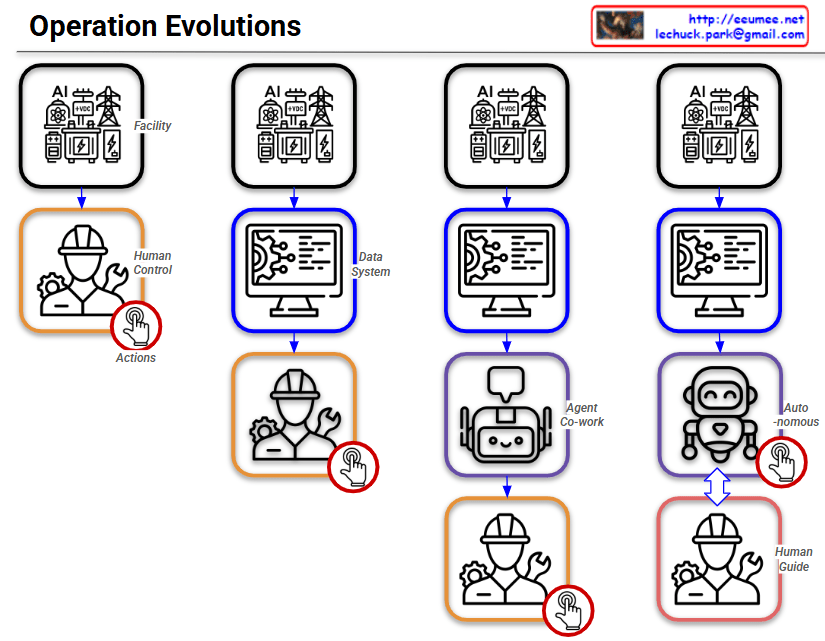
Operation Evolutions

By following the red circle with the ‘Actions’ (clicking hand) icon, you can easily track how the control and operational authority shift throughout the four stages.

Stage 1: Human Control

  • Structure: Facility ➡️ Human Control
  • Description: This represents the most traditional, manual approach. Without a centralized data system, human operators directly monitor the facility’s status and manually execute all Actions based on their physical observations and judgment.

Stage 2: Data System

  • Structure: Facility ➡️ Data System ➡️ Human Control
  • Description: A monitoring or data system (like a dashboard) is introduced. Humans now rely on the data collected by the system to understand the facility’s condition. However, the final Actions are still manually performed by humans.

Stage 3: Agent Co-work

  • Structure: Facility ➡️ Data System ➡️ Agent Co-work ➡️ Human Control
  • Description: An AI Agent is introduced as an intermediary between the data system and the human operator. The AI analyzes the data and provides insights, recommendations, or assistance. Even with this support, the final decision-making and physical Actions remain entirely the human’s responsibility.

Stage 4: Autonomous (Auto-nomous)

  • Structure: Facility ➡️ Data System ➡️ Auto-nomous ↔️ Human Guide
  • Description: This is the ultimate stage of operational evolution. The authority to execute Actions has shifted from the human to the AI. The AI analyzes data, makes independent decisions, and autonomously controls the facility. The human’s role transitions from a direct controller to a ‘Human Guide’, supervising the AI and providing high-level directives. The two-way arrow indicates a continuous, interactive feedback loop where the human and AI collaborate to refine and optimize the system.

Summary:

This slide intuitively illustrates a paradigm shift in infrastructure operations: progressing from Direct Human Intervention ➡️ System-Assisted Cognition ➡️ AI-Assisted Operations (Co-work) ➡️ Fully Autonomous AI Control with Human Supervision.

#AIOps #AutonomousOperations #TechEvolution #DigitalTransformation #DataCenter #FacilityManagement #InfrastructureAutomation #SmartFacilities #AIAgents #FutureOfWork #HumanAndAI #Automation

with Gemini