CRITICAL RAPID RESPONSE CHALLENGES

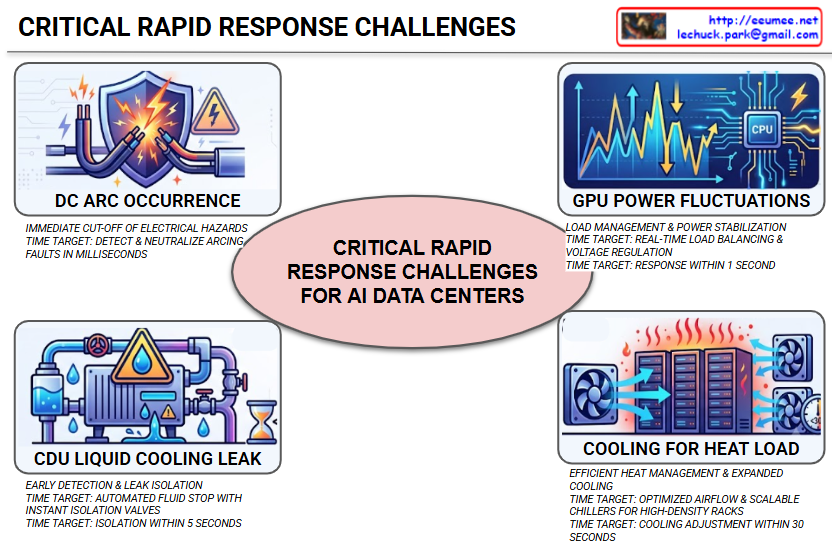
This image is an infographic structured around the central core theme, “CRITICAL RAPID RESPONSE CHALLENGES FOR AI DATA CENTERS,” presented within an oval, under the general title “CRITICAL RAPID RESPONSE CHALLENGES.”

It conveys the crucial message that as AI technology advancements cause data center power densities and heat loads to skyrocket, an extremely rapid response is absolutely essential whenever unexpected equipment failures or hazardous situations occur. Surrounding the central core theme, four specific threat scenarios and their target response times are detailed with corresponding visual icons.It conveys the crucial message that as AI technology advancements cause data center power densities and heat loads to skyrocket, an extremely rapid response is absolutely essential whenever unexpected equipment failures or hazardous situations occur. Surrounding the central core theme, four specific threat scenarios and their target response times are detailed with corresponding visual icons.

  1. DC ARC OCCURRENCE – Top Left:
    • Visual Elements: Powerful sparks (arcs) are flying between electrical cables, with a shield and a warning sign featuring a lightning bolt symbol blocking them.
    • Description: An arc, which is a luminous electrical discharge across a gap in a circuit, poses a severe fire hazard. The infographic calls for an immediate cut-off of electrical hazards and specifically sets a target time to detect and neutralize arcing faults in milliseconds.
  2. GPU POWER FLUCTUATIONS – Top Right:
    • Visual Elements: A combination of a wildly fluctuating line graph, a CPU chip icon labeled ‘CPU’, and a lightning bolt symbol.
    • Description: GPUs performing high-performance AI computations consume massive amounts of power, and consequently, the fluctuations in their power supply are significant. This can lead to system instability. To address this, load management and power stabilization are required, with a target response within 1 second achieved through real-time load balancing and voltage regulation.
  3. CDU LIQUID COOLING LEAK – Bottom Left:
    • Visual Elements: A cooling system (CDU, Coolant Distribution Unit) composed of pipes, a pump, and a tank is actively dripping water droplets, accompanied by a warning triangle and an hourglass icon.
    • Description: A leak in the liquid cooling system used to cool high-density server racks can be fatal to sensitive electronic equipment. Early detection and leak isolation are the top priority, with a target to achieve isolation within 5 seconds by implementing an automated fluid stop with instant isolation valves.
  4. COOLING FOR HEAT LOAD – Bottom Right:
    • Visual Elements: Hot heat icons are rising above multiple server racks, while powerful cooling fans around them are operating to circulate the air.
    • Description: Controlling the immense heat generated by the massive computations of AI servers is a cornerstone of data center operations. There is a need for efficient heat management and expanded cooling systems, with a target to complete a cooling adjustment within 30 seconds through optimized airflow and scalable chillers for high-density racks.

Summary

This infographic highlights four fatal risk factors related to power and thermal management that AI-dedicated data centers face. The key takeaway is the critical need for an extremely rapid, automated response, ranging from milliseconds to tens of seconds, when these issues occur to prevent major catastrophes such as system downtime or fire.This infographic highlights four fatal risk factors related to power and thermal management that AI-dedicated data centers face. The key takeaway is the critical need for an extremely rapid, automated response, ranging from milliseconds to tens of seconds, when these issues occur to prevent major catastrophes such as system downtime or fire.

#AIDataCenter #DataCenterEquipment #RapidResponse #DCArc #GPUPowerFluctuations #LiquidCoolingLeak #HeatLoadManagement #DataCenterSafety #SmartDataCenter #ITInfrastructure

With Gemini
DC Data Service Model


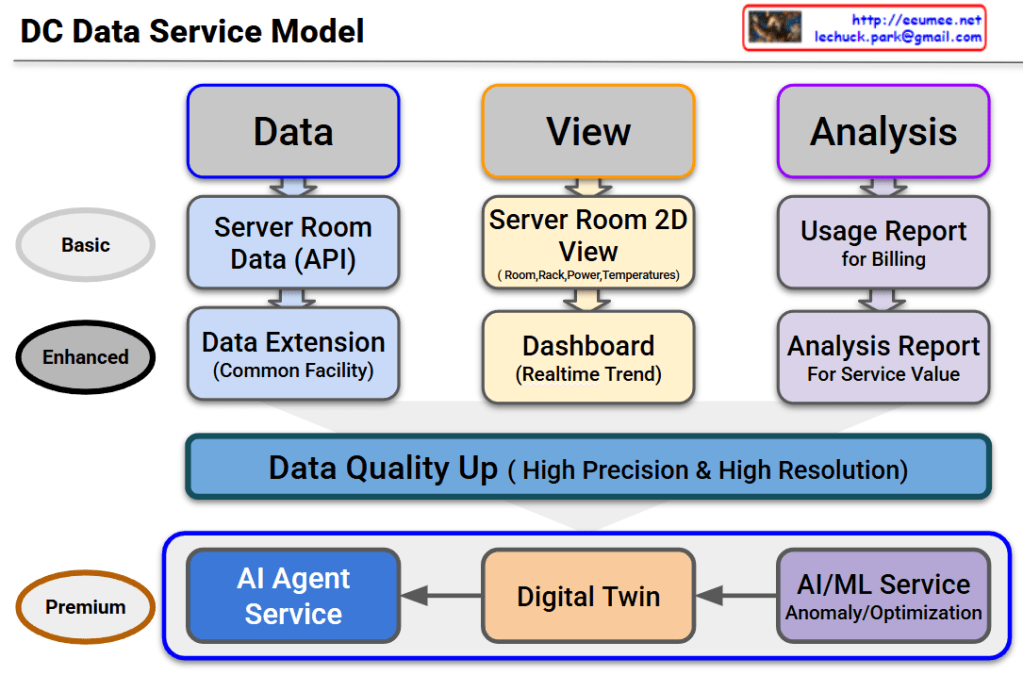
DC Data Service Model Overview

This diagram outlines the evolutionary roadmap of a Data Center (DC) Data Service Model. It illustrates how data center operations advance from basic monitoring to a highly autonomous, AI-driven environment. The model is structured across three functional pillars—Data, View, and Analysis—and progresses through three key service tiers.

Here is a breakdown of the evolving stages:

1. Basic Tier (The Foundation)

This is the foundational level, focusing on essential monitoring and billing.

  • Data: It begins with collecting Server Room Data via APIs.
  • View: Operators use a Server Room 2D View to track basic statuses like room layouts, rack placement, power consumption, and temperatures.
  • Analysis: The collected data is used to generate a basic Usage Report, primarily for customer billing.

2. Enhanced Tier (Real-time & Expanded Scope)

This tier broadens the monitoring scope and provides deeper operational insights.

  • Data: Data collection is expanded beyond the server room to include the Common Facility (Data Extension).
  • View: The user interface upgrades to a dynamic Dashboard that displays real-time operational trends.
  • Analysis: Reporting evolves into an Analysis Report, designed to extract deeper insights and improve overall service value.

3. The Bridge: Data Quality Up

Before transitioning to the ultimate AI-driven tier, there is a critical prerequisite layer. To effectively utilize AI, the system must secure data of High Precision & High Resolution. High-quality data is the fuel for the advanced services that follow.

4. Premium Tier (AI Agent as the Ultimate Orchestrator)

This is the ultimate goal of the model. The updated diagram highlights a clear, sequential flow where each advanced technology builds upon the last, culminating in a comprehensive AI Agent Service:

  • AI/ML Service: The high-quality data is first processed here to automatically detect anomalies and calculate optimizations (e.g., maximizing cooling and power efficiency).
  • Digital Twin: The analytical insights from the AI/ML layer are then integrated into a Digital Twin—a virtual, highly accurate replica of the physical data center used for real-time simulation and spatial monitoring.
  • AI Agent Service: This is the final and most critical layer. The AI Agent does not just sit alongside the other tools; it acts as the central brain. Through this final Agent Service, the capabilities of all preceding services are expanded and put into action. By leveraging the predictive power of the AI/ML models and the comprehensive visibility of the Digital Twin, the AI Agent can autonomously manage, resolve issues, and optimize the data center, maximizing the ultimate value of the entire data pipeline.

#DataCenter #DCIM #AIAgent #DigitalTwin #MachineLearning #ITOperations #TechInfrastructure #FutureOfTech #SmartDataCenter

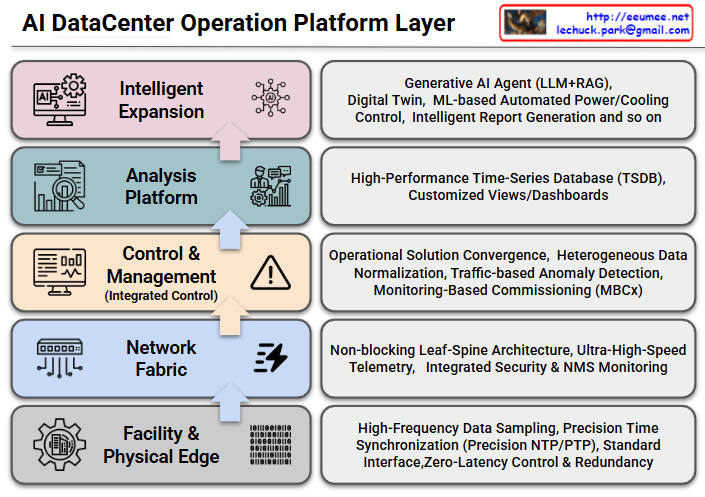
AI Data Center Operation Platform Layer

The provided image illustrates the architecture of an AI DataCenter Operation Platform, mapping it out in five distinct stages from the physical foundation layer up to the top-tier artificial intelligence application layer.

The upward-pointing arrows depict the flow of raw data collected from the infrastructure, demonstrating the system’s upward evolution and how the data is ultimately utilized intelligently by AI.

Here is the breakdown of the core roles and components of each layer:

  • Layer 1: Facility & Physical Edge
    • Role: The foundational layer responsible for collecting data and controlling the physical infrastructure equipment of the data center, such as power and cooling systems.
    • Key Elements: High-Frequency Data Sampling, Precision Time Synchronization (Precision NTP/PTP), Standard Interfaces, and Zero-Latency Control & Redundancy. This layer focuses on extracting data and issuing control commands to hardware with extreme speed and accuracy.
  • Layer 2: Network Fabric
    • Role: The neural network of the data center. It reliably and rapidly transmits the massive amounts of collected data to the upper platforms without bottlenecks.
    • Key Elements: Non-blocking Leaf-Spine Architecture, Ultra-High-Speed Telemetry, and Integrated Security & NMS (Network Management System) Monitoring. These elements work together to efficiently handle large-scale traffic.
  • Layer 3: Control & Management (Integrated Control)
    • Role: The layer that integrates and normalizes heterogeneous data streaming in from various facilities and solutions to execute practical operations and management.
    • Key Elements: Operational Solution Convergence, Heterogeneous Data Normalization, Traffic-based Anomaly Detection, and Monitoring-Based Commissioning (MBCx). It acts as a critical gateway to identify infrastructure issues early and improve overall operational efficiency.
  • Layer 4: Analysis Platform
    • Role: The stage where refined data is stored, analyzed, and visualized, allowing administrators to intuitively grasp the system’s status at a glance.
    • Key Elements: Utilizes a High-Performance Time-Series Database (TSDB) to record state changes over time and provides Customized Views/Dashboards for tailored monitoring.
  • Layer 5: Intelligent Expansion
    • Role: The ultimate destination of this platform. It is the highest layer where AI autonomously operates and optimizes the data center, leveraging the well-organized data provided by the lower layers.
    • Key Elements: Generative AI Agent (LLM+RAG), Digital Twin technology, ML-based Automated Power/Cooling Control, and Intelligent Report Generation.

This blueprint clearly demonstrates the overall solution architecture: precisely collecting and transmitting raw data from hardware facilities (Layers 1-2), standardizing, storing, and analyzing that data (Layers 3-4), and ultimately achieving advanced, autonomous operations through intelligent, automatic control of power and cooling systems via a Generative AI Agent (Layer 5).


#AIDataCenter #AIOps #DataCenterManagement #GenerativeAI #DigitalTwin #NetworkFabric #ITInfrastructure #SmartDataCenter #MachineLearning #TechArchitecture

With Gemini

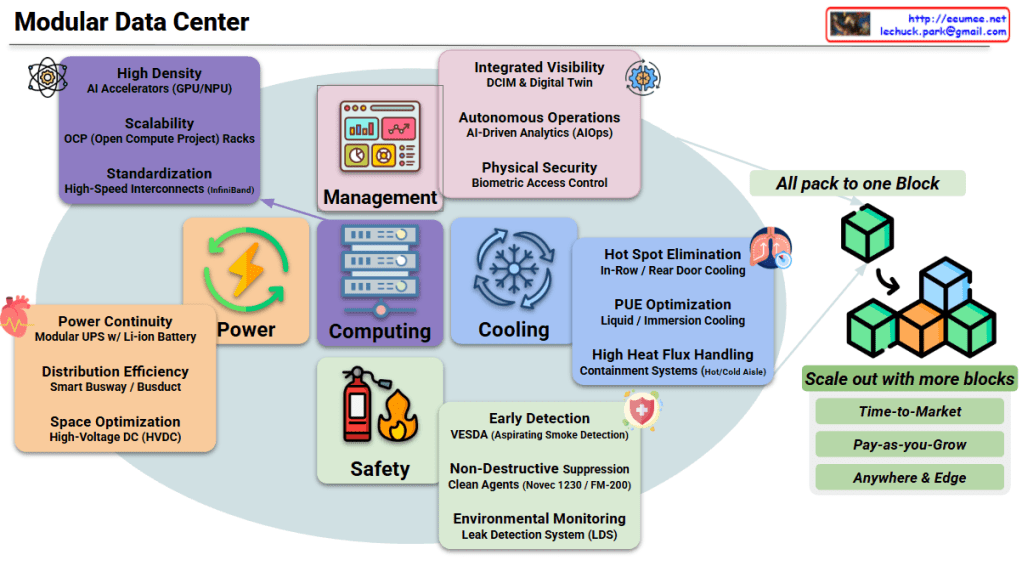
Modular Data Center

Modular Data Center Architecture Analysis

This image illustrates a comprehensive Modular Data Center architecture designed specifically for modern AI/ML workloads, showcasing integrated systems and their key capabilities.

Core Components

1. Management Layer

  • Integrated Visibility: DCIM & Digital Twin for real-time monitoring
  • Autonomous Operations: AI-Driven Analytics (AIOps) for predictive maintenance
  • Physical Security: Biometric Access Control for enhanced protection

2. Computing Infrastructure

  • High Density AI Accelerators: GPU/NPU optimized for AI workloads
  • Scalability: OCP (Open Compute Project) Racks for standardized deployment
  • Standardization: High-Speed Interconnects (InfiniBand) for low-latency communication

3. Power Systems

  • Power Continuity: Modular UPS with Li-ion Battery for reliable uptime
  • Distribution Efficiency: Smart Busway/Busduct for optimized power delivery
  • Space Optimization: High-Voltage DC (HVDC) for reduced footprint

4. Cooling Solutions

  • Hot Spot Elimination: In-Row/Rear Door Cooling for targeted heat removal
  • PUE Optimization: Liquid/Immersion Cooling for maximum efficiency
  • High Heat Flux Handling: Containment Systems (Hot/Cold Aisle) for AI density

5. Safety & Environmental

  • Early Detection: VESDA (Very Early Smoke Detection Apparatus)
  • Non-Destructive Suppression: Clean Agents (Novec 1230/FM-200)
  • Environmental Monitoring: Leak Detection System (LDS)

Why Modular DC is Critical for AI Data Centers

Speed & Agility

Traditional data centers take 18-24 months to build, but AI demands are exploding NOW. Modular DCs deploy in 3-6 months, allowing organizations to capture market opportunities and respond to rapidly evolving AI compute requirements without lengthy construction cycles.

AI-Specific Thermal Challenges

AI workloads generate 3-5x more heat per rack (30-100kW) compared to traditional servers (5-10kW). Modular designs integrate advanced liquid cooling and containment systems from day one, purpose-built to handle GPU/NPU thermal density that would overwhelm conventional infrastructure.

Elastic Scalability

AI projects often start experimental but can scale exponentially. The “pay-as-you-grow” model lets organizations deploy one block initially, then add capacity incrementally as models grow—avoiding massive upfront capital while maintaining consistent architecture and avoiding stranded capacity.

Edge AI Deployment

AI inference increasingly happens at the edge for latency-sensitive applications (autonomous vehicles, smart manufacturing). Modular DCs’ compact, self-contained design enables AI deployment anywhere—from remote locations to urban centers—with full data center capabilities in a standardized package.

Operational Efficiency

AI workloads demand maximum PUE efficiency to manage operational costs. Modular DCs achieve PUE of 1.1-1.3 through integrated cooling optimization, HVDC power distribution, and AI-driven management—versus 1.5-2.0 in traditional facilities—critical when GPU clusters consume megawatts.

Key Advantages

📦 “All pack to one Block” – Complete infrastructure in pre-integrated modules 🧩 “Scale out with more blocks” – Linear, predictable expansion without redesign

  • ⏱️ Time-to-Market: 4-6x faster deployment vs traditional builds
  • 💰 Pay-as-you-Grow: CapEx aligned with revenue/demand curves
  • 🌍 Anywhere & Edge: Containerized deployment for any location

Summary

Modular Data Centers are essential for AI infrastructure because they deliver pre-integrated, high-density compute, power, and cooling blocks that deploy 4-6x faster than traditional builds, enabling organizations to rapidly scale GPU clusters from prototype to production while maintaining optimal PUE efficiency and avoiding massive upfront capital investment in uncertain AI workload trajectories.

The modular approach specifically addresses AI’s unique challenges: extreme thermal density (30-100kW/rack), explosive demand growth, edge deployment requirements, and the need for liquid cooling integration—all packaged in standardized blocks that can be deployed anywhere in months rather than years.

This architecture transforms data center infrastructure from a multi-year construction project into an agile, scalable platform that matches the speed of AI innovation, allowing organizations to compete in the AI economy without betting the company on fixed infrastructure that may be obsolete before completion.


#ModularDataCenter #AIInfrastructure #DataCenterDesign #EdgeComputing #LiquidCooling #GPUComputing #HyperscaleAI #DataCenterModernization #AIWorkloads #GreenDataCenter #DCInfrastructure #SmartDataCenter #PUEOptimization #AIops #DigitalTwin #EdgeAI #DataCenterInnovation #CloudInfrastructure #EnterpriseAI #SustainableTech

With Claude