The 4 Core Pillars of AI Technology

This image is a highly structured infographic titled “4 CORE PILLARS OF AI TECHNOLOGY: A CONTINUOUS CYCLE.” It visually explains the architecture of an AI system and its interaction with humans. Arranged around a central AI engine, four primary domains are connected by dynamic arrows, illustrating a continuous, organic flow of information and feedback.

  1. Center – AI Framework & Reasoning: Situated at the very heart of the diagram as a diamond-shaped core, this represents the “brain” of the AI. It acts as the central hub that ingests data from all pillars, processes it, and generates reasoned outputs.
  2. Bottom Left – Numbers (Core Logic & Telemetry): Decorated with mathematical symbols, binary code, and various charts. This section symbolizes the quantitative foundation of AI—the raw data, understanding of change, and the prediction logic that form the physical and structural core of the system.
  3. Bottom Right – Text (Human Knowledge Base): Illustrated with books, documents, and scrolls. It represents the qualitative foundation: human knowledge, context, and language-based insights. This is how the AI learns to understand the nuances and accumulated wisdom of humanity.
  4. Middle Right – UX Output (Insights & Interface): Depicted as a digital dashboard featuring a robot chatbot icon and data summaries. This domain shows how complex AI computations are translated into user-friendly formats. It provides clear “Key Insights,” “Actionable Steps,” and summaries so humans can easily grasp the results.
  5. Top & Middle Left – Human Control & Data Verification: At the absolute top, a human figure in a suit stands as “The Ultimate Authority.” This highlights the human responsibility in rule setting, adding knowledge, and execution confirmation. On the left side, the imagery of hands meticulously analyzing a clipboard and charts—now clearly labeled “DATA VERIFICATION”—emphasizes the critical, hands-on role humans play in evaluating, auditing, and refining the AI’s output.

📌 Summary

This diagram intuitively maps the operational loop of modern AI: raw “Numbers” (logic) and qualitative “Text” (knowledge) feed into the AI engine, which then translates its findings into a user-friendly “UX Output.” Crucially, it highlights that this entire automated cycle is overseen, verified, and refined by humans. It serves as a powerful reminder that “Human-in-the-loop” remains the ultimate authority and the indispensable final step in ensuring AI reliability.

#AITechnology #ArtificialIntelligence #DataVerification #HumanInTheLoop #UXDesign #DataScience #TechTrends #AIInfographic

With Gemini
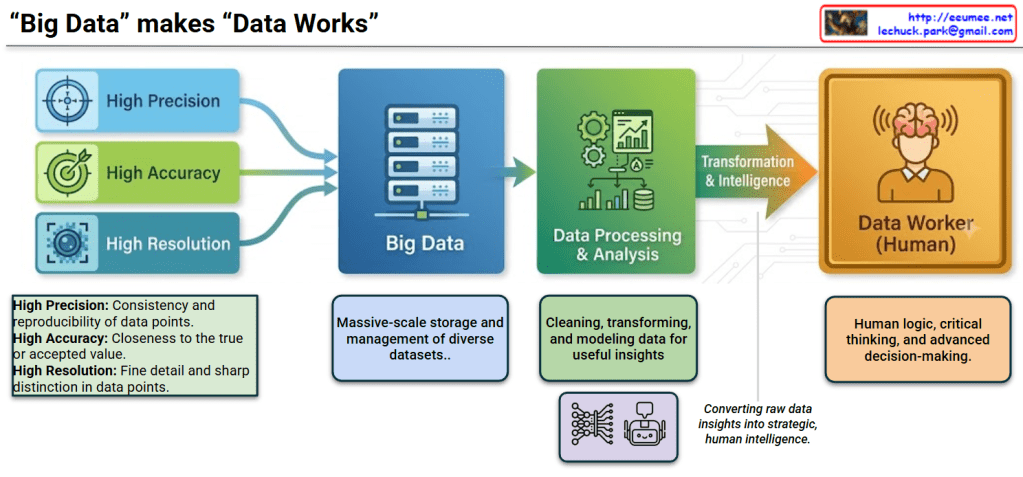
“Data” makes “Data Works”

The image illustrates the workflow of data processing and utilization under the title “Data” makes “Data Works”. It breaks down the journey from raw data input on the left to human decision-making on the right into four distinct stages.

📊 Detailed Image Breakdown

Step 1: Data Attributes (Input Stage) On the far left, three essential attributes of high-quality data are shown feeding into the Big Data system:

  • High Precision: Represented by a crosshair icon, this refers to the consistency and reproducibility of data points.
  • High Accuracy: Represented by a dart hitting a bullseye, indicating the closeness of data to the true or accepted value.
  • High Resolution: Represented by a camera lens icon, meaning fine detail and sharp distinction in data points.

Step 2: Big Data (Storage & Management)

  • Depicted by a server rack icon, this stage represents the destination for the high-quality inputs.
  • It highlights the massive-scale storage and management of diverse datasets.

Step 3: Data Processing & Analysis

  • Illustrated with gears and charts, this phase involves cleaning, transforming, and modeling data to extract useful insights.
  • The neural network and robot icons below this box suggest the heavy involvement of AI, automation, and machine learning in processing the data.

Step 4: Transformation & Intelligence ➔ Data Worker (Human)

  • An arrow labeled “Transformation & Intelligence” bridges the gap between machines and humans, with a note stating it is “Converting raw data insights into strategic, human intelligence.”
  • The workflow culminates at the Data Worker (Human), represented by a person with a glowing brain. This emphasizes that human logic, critical thinking, and advanced decision-making are the ultimate goals and necessities, even with advanced data systems.

📝 Summary

This diagram illustrates the comprehensive workflow of modern data science. It shows how highly precise, accurate, and high-resolution data is collected into Big Data systems, processed and modeled using analytical and AI tools, and ultimately transformed into actionable intelligence that empowers a human Data Worker to apply critical thinking and make strategic decisions.

#BigData #DataAnalysis #DataScience #ArtificialIntelligence #DataWorker #DecisionMaking #DataVisualization

With Gemini

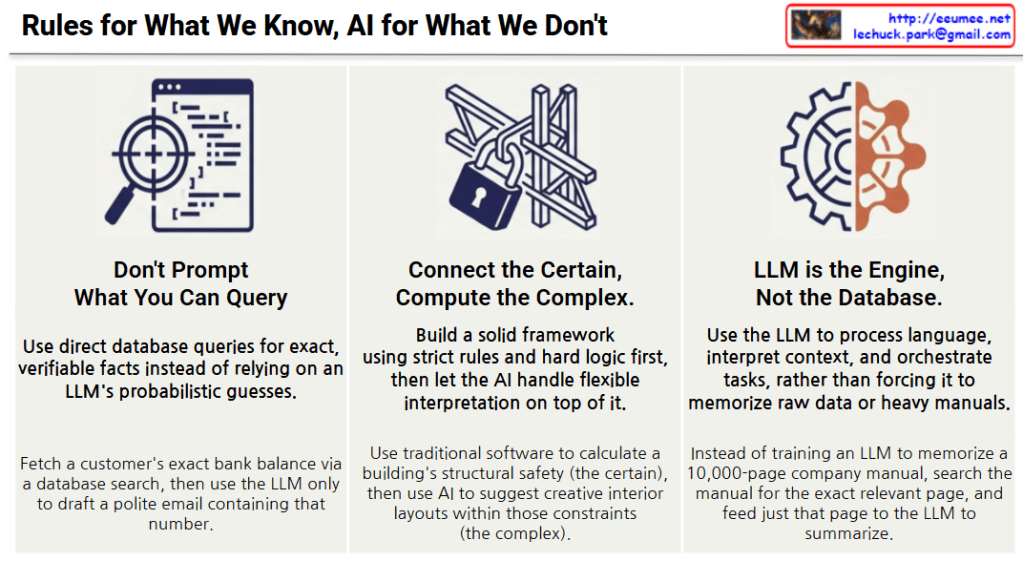
Rules for What We Know, AI for What We Don’t 

This image presents a practical guide on how to effectively integrate Artificial Intelligence, specifically Large Language Models (LLMs), into software systems. The overarching theme is “Rules for What We Know, AI for What We Don’t,” which emphasizes using reliable, traditional computing for hard facts and reserving AI for complex reasoning and interpretation.

1. Don’t Prompt What You Can Query

This principle warns against using AI to retrieve exact data. Because LLMs generate responses based on probabilities, they can sometimes guess incorrectly or hallucinate. If you need a verified fact—like a user’s bank balance—you should use a standard database search to fetch that exact number. Once you have the accurate data, you can then pass it to the AI to draft a natural, polite response.

2. Connect the Certain, Compute the Complex

This section suggests building a hybrid approach to problem-solving. You should establish a strict, rule-based foundation (the “certain”) using traditional logic, math, or physics. Once that solid framework is in place, you let the AI operate on top of it to handle creative or flexible tasks (the “complex”). For example, use traditional software to ensure a building is structurally safe, and then use AI to design creative interior layouts within those safe boundaries.

3. LLM is the Engine, Not the Database

This final point clarifies the true role of an LLM: it is a processor, not a storage drive. You shouldn’t try to force an AI to memorize massive amounts of raw data, like a 10,000-page company manual. Instead, use a search system to find the exact page you need, and then feed just that relevant text into the LLM. The AI acts as the “engine” to read, understand, and summarize that specific information for you.

Summary

To build reliable AI applications, rely on traditional databases and strict logic for factual retrieval and structural constraints. Use LLMs strictly as reasoning and processing engines to interpret context, draft text, and solve complex problems based on the hard facts you provide them.

#AIArchitecture #LLM #ArtificialIntelligence #SoftwareEngineering #DataScience #PromptEngineering #GenerativeAI

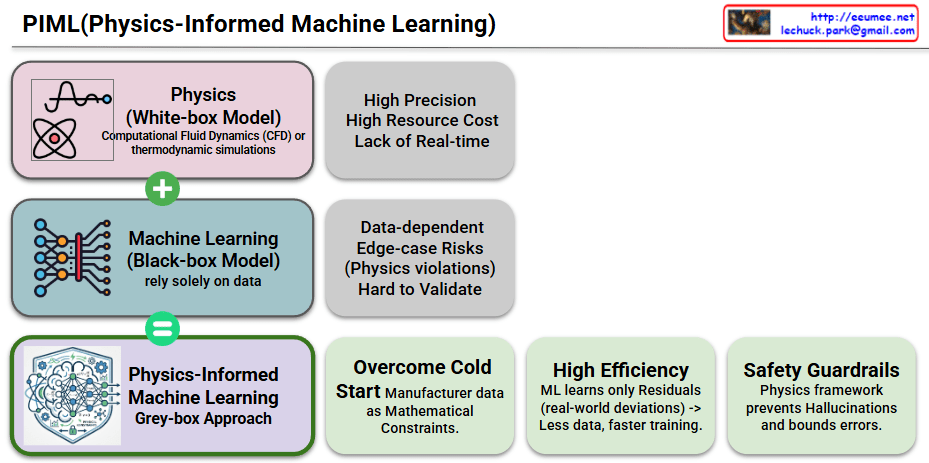
PIML(Physics-Informed Machine Learning)

PIML (Physics-Informed Machine Learning) Explained

This diagram illustrates how PIML (Physics-Informed Machine Learning) combines the strengths of physics-based models and data-driven machine learning to create a more powerful and reliable approach.


1. Top: Physics (White-box Model)

  • Definition: These are models where the underlying principles are fully explained by mathematical equations, such as Computational Fluid Dynamics (CFD) or thermodynamic simulations.
  • Characteristics:
    • High Precision: They are very accurate because they are based on fundamental physical laws.
    • High Resource Cost: They are computationally intensive, requiring significant processing power and time.
    • Lack of Real-time Processing: Complex simulations are difficult to use for real-time prediction or control.

2. Middle: Machine Learning (Black-box Model)

  • Definition: These models rely solely on large amounts of training data to find correlations and make predictions, without using underlying physical principles.
  • Characteristics:
    • Data-dependent: Their performance depends heavily on the quality and quantity of the data they are trained on.
    • Edge-case Risks: In situations not covered by the data (edge cases), they can make illogical predictions that violate physical laws.
    • Hard to Validate: It is difficult to understand their internal workings, making it challenging to verify the reliability of their results.

3. Bottom: Physics-Informed Machine Learning (Grey-box Approach)

  • Definition: This approach integrates the knowledge of physical laws (equations) into a machine learning model as mathematical constraints, combining the best of both worlds.
  • Benefits:
    • Overcome Cold Start Problem: By using existing knowledge like mathematical constraints, PIML can function even when training data is scarce, effectively addressing the initial (“Cold Start”) state.
    • High Efficiency: Instead of learning physics from scratch, the ML model focuses on learning only the residuals (real-world deviations) between the physics-based model and actual data. This makes learning faster and more efficient with less data.
    • Safety Guardrails: The integrated physics framework acts as a set of safety guardrails, providing constraints that prevent the model from making physically impossible predictions (“Hallucinations”) and bounding errors to ensure safety.

#AI #PIML #MachineLearning #Physics #HybridAI #DataScience #ExplainableAI #XAI #ComputationalPhysics #Simulation

with Gemini