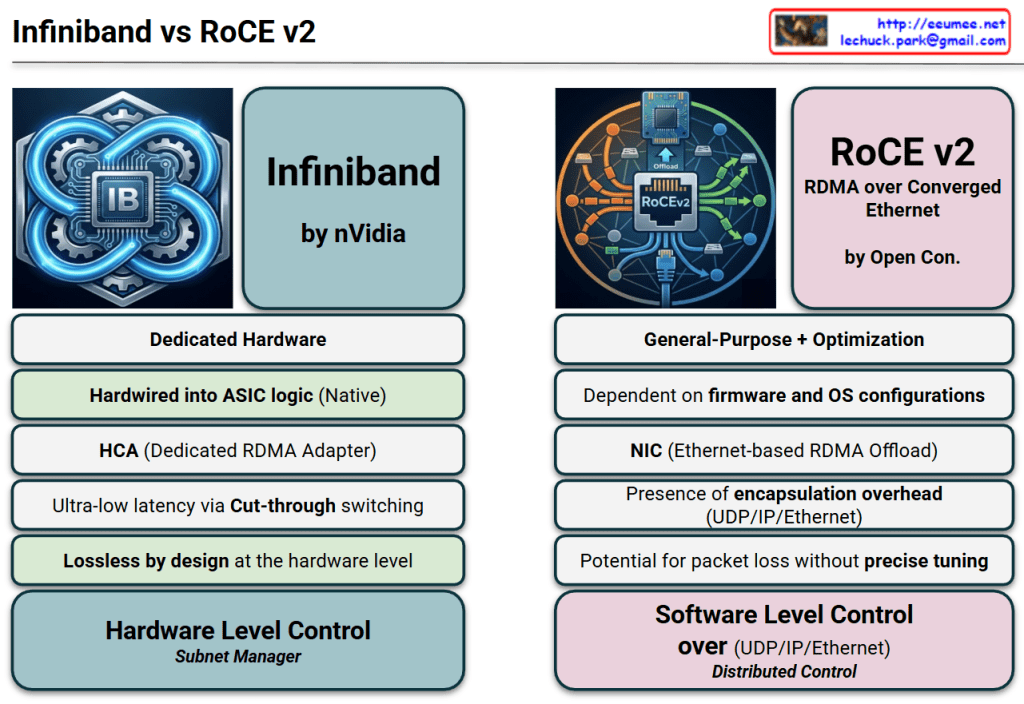
Infiniband vs RoCE v2

This image provides a technical comparison between InfiniBand and RoCE v2 (RDMA over Converged Ethernet), the two dominant networking protocols used in modern AI data centers and High-Performance Computing (HPC) environments.


1. Architectural Philosophy

  • InfiniBand (Dedicated Hardware): Designed from the ground up specifically for high-throughput, low-latency communication. It is a proprietary ecosystem largely driven by NVIDIA (Mellanox).
  • RoCE v2 (General-Purpose + Optimization): An evolution of standard Ethernet designed to bring RDMA (Remote Direct Memory Access) capabilities to traditional network infrastructures. It is backed by the Open Consortium.

2. Hardware vs. Software Logic

  • Hardwired ASIC (InfiniBand): The protocol logic is baked directly into the silicon. This “Native” approach ensures consistent performance with minimal jitter.
  • Firmware & OS Dependent (RoCE v2): Relies more heavily on the NIC’s firmware and operating system configurations, making it more flexible but potentially more complex to stabilize.

3. Data Transfer Efficiency

  • Ultra-low Latency (InfiniBand): Utilizes Cut-through switching, where the switch starts forwarding the packet as soon as the destination address is read, without waiting for the full packet to arrive.
  • Encapsulation Overhead (RoCE v2): Because it runs on Ethernet, it must wrap RDMA data in UDP/IP/Ethernet headers. This adds “overhead” (extra data bits) and processing time compared to the leaner InfiniBand frames.

4. Reliability and Loss Management

  • Lossless by Design (InfiniBand): It uses a credit-based flow control mechanism at the hardware level, ensuring that a sender never transmits data unless the receiver has room to buffer it. This guarantees zero packet loss.
  • Tuning-Dependent (RoCE v2): Ethernet is natively “lossy.” To make RoCE v2 work effectively, the network must be “Converged” using complex features like PFC (Priority Flow Control) and ECN (Explicit Congestion Notification). Without precise tuning, performance can collapse during congestion.

5. Network Management

  • Subnet Manager (InfiniBand): Uses a centralized “Subnet Manager” to discover the topology and manage routing, which simplifies the management of massive GPU clusters.
  • Distributed Control (RoCE v2): Functions like a traditional IP network where routing and control are distributed across the switches and routers.

Comparison Summary

FeatureInfiniBandRoCE v2
Primary DriverPerformance & StabilityCost-effectiveness & Compatibility
ComplexityPlug-and-play (within IB ecosystem)Requires expert-level network tuning
LatencyAbsolute LowestLow (but higher than IB)
ScalabilityHigh (specifically for AI/HPC)High (standard Ethernet scalability)

Design & Logic: InfiniBand is a dedicated, hardware-native solution for ultra-low latency, whereas RoCE v2 adapts general-purpose Ethernet for RDMA through software-defined optimization and firmware.

Efficiency & Reliability: InfiniBand is “lossless by design” with minimal overhead via cut-through switching, while RoCE v2 incurs encapsulation overhead and requires precise network tuning to prevent packet loss.

Control & Management: InfiniBand utilizes centralized hardware-level management (Subnet Manager) for peak stability, while RoCE v2 relies on distributed software-level control over standard UDP/IP/Ethernet stacks.

#InfiniBand #RoCEv2 #RDMA #AIDataCenter #NetworkingArchitecture #NVIDIA #HighPerformanceComputing #GPUCluster #DataCenterDesign #Ethernet #AITraining
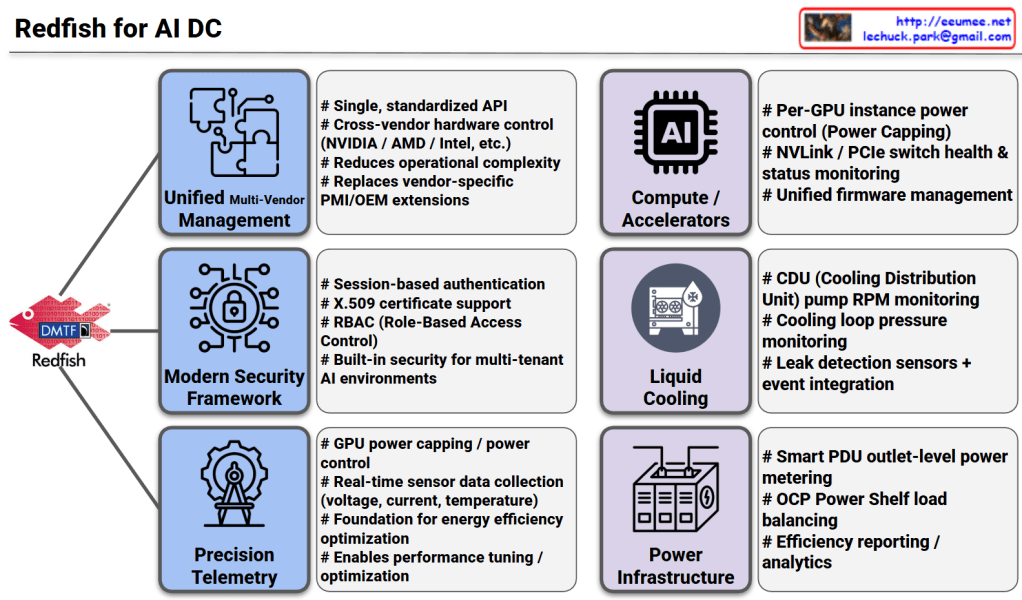
Redfish for AI DC

This image illustrates the pivotal role of the Redfish API (developed by DMTF) as the standardized management backbone for modern AI Data Centers (AI DC). As AI workloads demand unprecedented levels of power and cooling, Redfish moves beyond traditional server management to provide a unified framework for the entire infrastructure stack.


1. Management & Security Framework (Left Column)

  • Unified Multi-Vendor Management:
    • Acts as a single, standardized API to manage diverse hardware from different vendors (NVIDIA, AMD, Intel, etc.).
    • It reduces operational complexity by replacing fragmented, vendor-specific IPMI or OEM extensions with a consistent interface.
  • Modern Security Framework:
    • Designed for multi-tenant AI environments where security is paramount.
    • Supports robust protocols like session-based authentication, X.509 certificates, and RBAC (Role-Based Access Control) to ensure only authorized entities can modify critical infrastructure.
  • Precision Telemetry:
    • Provides high-granularity, real-time data collection for voltage, current, and temperature.
    • This serves as the foundation for energy efficiency optimization and fine-tuning performance based on real-time hardware health.

2. Infrastructure & Hardware Control (Right Column)

  • Compute / Accelerators:
    • Enables per-GPU instance power capping, allowing operators to limit power consumption at a granular level.
    • Monitors the health of high-speed interconnects like NVLink and PCIe switches, and simplifies firmware lifecycle management across the cluster.
  • Liquid Cooling:
    • As AI chips run hotter, Redfish integrates with CDU (Cooling Distribution Unit) systems to monitor pump RPM and loop pressure.
    • It includes critical safety features like leak detection sensors and integrated event handling to prevent hardware damage.
  • Power Infrastructure:
    • Extends management to the rack level, including Smart PDU outlet metering and OCP (Open Compute Project) Power Shelf load balancing.
    • Facilitates advanced efficiency analytics to drive down PUE (Power Usage Effectiveness).

Summary

For an AI DC Optimization Architect, Redfish is the essential “language” that enables Software-Defined Infrastructure. By moving away from manual, siloed hardware management and toward this API-driven approach, data centers can achieve the extreme automation required to shift OPEX structures predominantly toward electricity costs rather than labor.

#AIDataCenter #RedfishAPI #DMTF #DataCenterInfrastructure #GPUComputing #LiquidCooling #SustainableIT #SmartPDU #OCP #InfrastructureAutomation #TechArchitecture #EnergyEfficiency


With Gemini

AI GPU Cost

AI GPU Service Cost Proof

This image outlines a framework for justifying the cost of AI GPU services (such as cloud or bare-metal leasing) by strictly proving performance quality. The core theme is “Transparency with Metrics,” demonstrating Stability and Efficiency through data rather than empty promises.

Here is a breakdown of the four key quadrants:

1. Clock Speed Consistency (Top Left)

  • Metric: Stable SM (Streaming Multiprocessor) Clock.
  • Meaning: This tracks the operating frequency of the GPU’s core compute units over time.
  • Significance: The graph should ideally be a flat line. Fluctuations indicate “clock jitter,” which leads to unpredictable training times and inconsistent performance. A stable clock proves the power delivery is clean and the workload is steady.

2. Zero Throttling Events (Top Right)

  • Metric: Count of ‘SW Power Cap’ and ‘Thermal Slowdown’ events.
  • Meaning: It verifies whether the GPU had to forcibly lower its performance (throttle) due to overheating or hitting power limits.
  • Significance: The goal is Zero (0). Any positive number means the infrastructure failed to support the GPU’s maximum potential, wasting the customer’s money and time.

3. Thermal Headroom (Bottom Left)

  • Metric: Temperature Margin (vs. $T_{limit}$).
    • (Note: The text box in the image incorrectly repeats “Streaming Multiprocessor Clock Changes,” likely a copy-paste error, but the gauge clearly indicates Temperature).
  • Meaning: It displays the gap between the current operating temperature and the GPU’s thermal limit.
  • Significance: Operating with a safe margin (headroom) prevents thermal throttling and ensures hardware longevity during long-running AI workloads.

4. Power Draw vs TDP (Bottom Right)

  • Metric: Max Power Utilization vs. Thermal Design Power (TDP).
    • (Note: The text box here also appears to be a copy-paste error from the top right, but the gauge represents Power/Watts).
  • Meaning: It measures how close the actual power consumption is to the GPU’s rated maximum (TDP).
  • Significance: If the power draw is consistently close to the TDP (e.g., 700W), it proves the GPU is being fully utilized. If it’s low despite a heavy workload, it suggests a bottleneck elsewhere (network, CPU, or power delivery issues).

Summary

  1. Objective: To validate service fees by providing transparent, data-driven proof of infrastructure quality.
  2. Key Metrics: Focuses on maintaining Stable Clocks, ensuring Zero Throttling, securing Thermal Headroom, and maximizing Power Utilization.
  3. Value: It acts as a technical SLA (Service Level Agreement), assuring users that the environment allows the GPUs to perform at 100% capacity without degradation.

#AIDataCenter #GPUOptimization #ServiceLevelAgreement #CloudInfrastructure #Nvidia #HighPerformanceComputing #DataCenterOps #GreenComputing #TechTransparency #AIInfrastructure

With Gemini

Ready For AI DC


Ready for AI DC

This slide illustrates the “Preparation and Operation Strategy for AI Data Centers (AI DC).”

In the era of Generative AI and Large Language Models (LLM), it outlines the drastic changes data centers face and proposes a specific three-stage operation strategy (Digitization, Solutions, Operations) to address them.

1. Left Side: AI “Extreme” Changes

Core Theme: AI Data Center for Generative AI & LLM

  • High Cost, High Risk:
    • Establishing and operating AI DCs involves immense costs due to expensive infrastructure like GPU servers.
    • It entails high power consumption and system complexity, leading to significant risks in case of failure.
  • New Techs for AI:
    • Unlike traditional centers, new power and cooling technologies (e.g., high-density racks, immersion cooling) and high-performance computing architectures are essential.

2. Right Side: AI Operation Strategy

Three solutions to overcome the “High Cost, High Risk, and New Tech” environment.

A. Digitization (Securing Data)

  • High Precision, High Resolution: Collecting precise, high-resolution operational data (e.g., second-level power usage, chip-level temperature) rather than rough averages.
  • Computing-Power-Cooling All-Relative Data: Securing integrated data to analyze the tight correlations between IT load (computing), power, and cooling systems.

B. Solutions (Adopting Tools)

  • “Living” Digital Twin: Building a digital twin linked in real-time to the actual data center for dynamic simulation and monitoring, going beyond static 3D modeling.
  • LLM AI Agent: Introducing LLM-based AI agents to assist or automate complex data center management tasks.

C. Operations (Innovating Processes)

  • Integration for Multi/Edge(s): Establishing a unified management system that covers not only centralized centers but also distributed multi-cloud and edge locations.
  • DevOps for the Fast: Applying agile DevOps methodologies to development and operations to adapt quickly to the rapidly changing AI infrastructure.

๐Ÿ’ก Summary & Key Takeaways

The slide suggests that traditional operating methods are unsustainable due to the costs and risks associated with AI workloads.

Success in the AI era requires precisely integrating IT and facility data (Digitization), utilizing advanced technologies like Digital Twins and AI Agents (Solutions), and adopting fast, integrated processes (Operations).


#AIDataCenter #AIDC #GenerativeAI #LLM #DataCenterStrategy #DigitalTwin #DevOps #AIInfrastructure #TechTrends #SmartOperations #EnergyEfficiency #EdgeComputing #AIInnovation

With Gemini

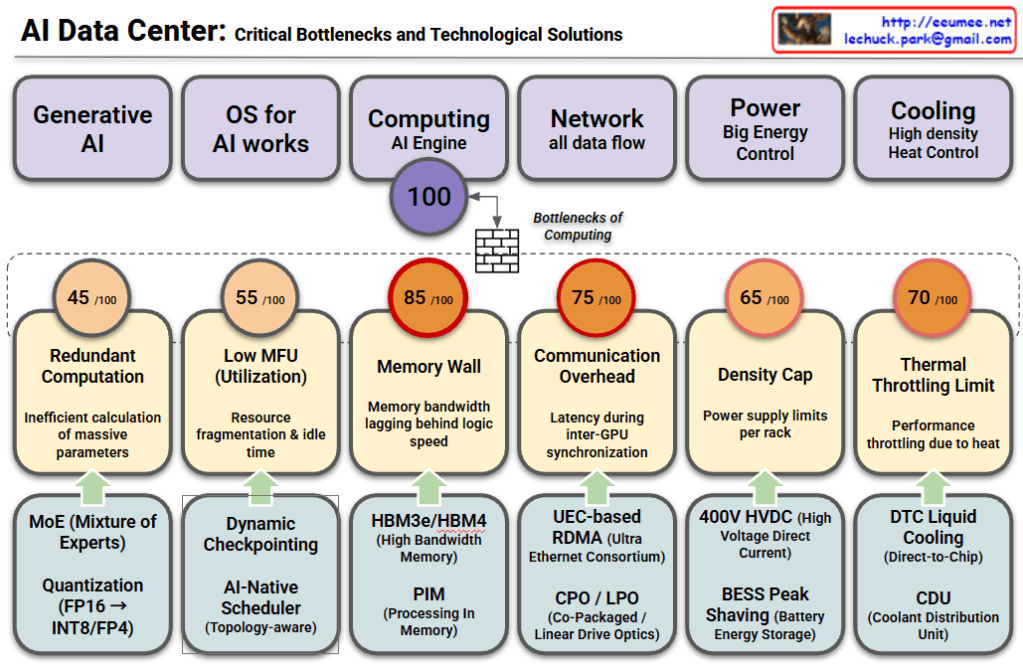
AI Data Center: Critical Bottlenecks and Technological Solutions


AI Data Center: Critical Bottlenecks and Technological Solutions

This chart analyzes the major challenges facing modern AI Data Centers across six key domains. It outlines the [Domain] โ†’ [Bottleneck/Problem] โ†’ [Solution] flow, indicating the severity of each bottleneck with a score out of 100.

1. Generative AI

  • Bottleneck (45/100): Redundant Computation
    • Inefficiencies occur when calculating massive parameters for large models.
  • Solutions:
    • MoE (Mixture of Experts): Uses only relevant sub-models (experts) for specific tasks to reduce computation.
    • Quantization (FP16 โ†’ INT8/FP4): Reduces data precision to speed up processing and save memory.

2. OS for AI Works

  • Bottleneck (55/100): Low MFU (Model Flops Utilization)
    • Issues with resource fragmentation and idle time result in underutilization of hardware.
  • Solutions:
    • Dynamic Checkpointing: Efficiently saves model states during training.
    • AI-Native Scheduler: Optimizes task distribution based on network topology.

3. Computing / AI Engine (Most Critical)

  • Bottleneck (85/100): Memory Wall
    • Marked as the most severe bottleneck, where memory bandwidth cannot keep up with the speed of logic processors.
  • Solutions:
    • HBM3e/HBM4: Next-generation High Bandwidth Memory.
    • PIM (Processing In Memory): Performs calculations directly within memory to reduce data movement.

4. Network

  • Bottleneck (75/100): Communication Overhead
    • Latency issues arise during synchronization between multiple GPUs.
  • Solutions:
    • UEC-based RDMA: Ultra Ethernet Consortium standards for faster direct memory access.
    • CPO / LPO: Advanced optics (Co-Packaged/Linear Drive) to improve data transmission efficiency.

5. Power

  • Bottleneck (65/100): Density Cap
    • Physical limits on how much power can be supplied per server rack.
  • Solutions:
    • 400V HVDC: High Voltage Direct Current for efficient power delivery.
    • BESS Peak Shaving: Using Battery Energy Storage Systems to manage peak power loads.

6. Cooling

  • Bottleneck (70/100): Thermal Throttling Limit
    • Performance drops (throttling) caused by excessive heat in high-density racks.
  • Solutions:
    • DTC Liquid Cooling: Direct-to-Chip liquid cooling technologies.
    • CDU: Coolant Distribution Units for effective heat management.

Summary

  1. The “Memory Wall” (85/100) is identified as the most critical bottleneck in AI Data Centers, meaning memory bandwidth is the primary constraint on performance.
  2. To overcome these limits, the industry is adopting advanced hardware like HBM and Liquid Cooling, alongside software optimizations like MoE and Quantization.
  3. Scaling AI infrastructure requires a holistic approach that addresses computing, networking, power efficiency, and thermal management simultaneously.

#AIDataCenter #ArtificialIntelligence #MemoryWall #HBM #LiquidCooling #GenerativeAI #TechTrends #AIInfrastructure #Semiconductor #CloudComputing

With Gemini

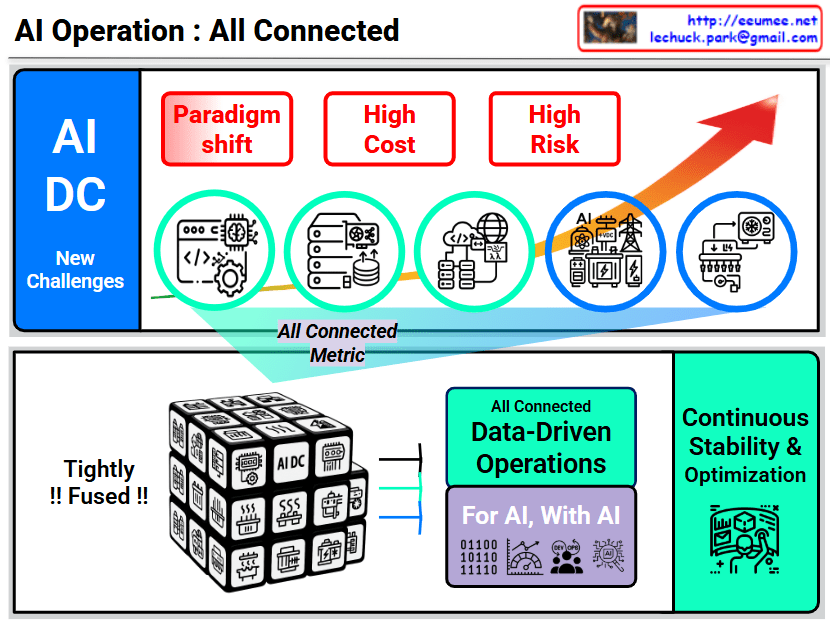
AI Operation : All Connected

AI Operation: All Connected – Image Analysis

This diagram explains the operational paradigm shift in AI Data Centers (AI DC).

Top Section: New Challenges

AI DC Characteristics:

  • Paradigm shift: Fundamental change in operations for the AI era
  • High Cost: Massive investment required for GPUs, infrastructure, etc.
  • High Risk: Greater impact during outages and increased complexity

Five Core Components of AI DC (leftโ†’right):

  1. Software: AI models, application development
  2. Computing: GPUs, servers, and computational resources
  3. Network: Data transmission and communication infrastructure
  4. Power: High-density power supply and management (highlighted in orange)
  5. Cooling: Heat management and cooling systems

โ†’ These five elements are interconnected through the “All Connected Metric”

Bottom Section: Integrated Operations Solution

Core Concept:

๐Ÿ“ฆ Tightly Fused Rubik’s Cube

  • The five core components (Software, Computing, Network, Power, Cooling) are intricately intertwined like a Rubik’s cube
  • Changes or issues in one element affect all other elements due to tight coupling

๐ŸŽฏ All Connected Data-Driven Operations

  • Data-driven integrated operations: Collecting and analyzing data from all connected elements
  • “For AI, With AI”: Operating the data center itself using AI technology for AI workloads

โœ… Continuous Stability & Optimization

  • Ensuring continuous stability
  • Real-time monitoring and optimization

Key Message

AI data centers have five core componentsโ€”Software, Computing, Network, Power, and Coolingโ€”that are tightly fused together. To effectively manage this complex system, a data-centric approach that integrates and analyzes data from all components is essential, enabling continuous stability and optimization.


Summary

AI data centers are characterized by tightly coupled components (software, computing, network, power, cooling) that create high complexity, cost, and risk. This interconnected system requires data-driven operations that leverage AI to monitor and optimize all elements simultaneously. The goal is achieving continuous stability and optimization through integrated, real-time management of all connected metrics.

#AIDataCenter #DataDrivenOps #AIInfrastructure #DataCenterOptimization #TightlyFused #AIOperations #HybridInfrastructure #IntelligentOps #AIforAI #DataCenterManagement #MLOps #AIOps #PowerManagement #CoolingOptimization #NetworkInfrastructure

Data Center Shift with AI

Data Center Shift with AI

This diagram illustrates how data centers are transforming as they enter the AI era.

๐Ÿ“… Timeline of Technological Evolution

The top section shows major technology revolutions and their timelines:

  • Internet ’95 (Internet era)
  • Mobile ’07 (Mobile era)
  • Cloud ’10 (Cloud era)
  • Blockchain
  • AI(LLM) ’22 (Large Language Model-based AI era)

๐Ÿข Traditional Data Center Components

Conventional data centers consisted of the following core components:

  • Software
  • Server
  • Network
  • Power
  • Cooling

These were designed as relatively independent layers.

๐Ÿš€ New Requirements in the AI Era

With the introduction of AI (especially LLMs), data centers require specialized infrastructure:

  1. LLM Model – Operating large language models
  2. GPU – High-performance graphics processing units (essential for AI computations)
  3. High B/W – High-bandwidth networks (for processing large volumes of data)
  4. SMR/HVDC – Switched-Mode Rectifier/High-Voltage Direct Current power systems
  5. Liquid/CDU – Liquid cooling/Cooling Distribution Units (for cooling high-heat GPUs)

๐Ÿ”— Key Characteristic of AI Data Centers: Integrated Design

The circular connection in the center of the diagram represents the most critical feature of AI data centers:

Tight Interdependency between SW/Computing/Network โ†” Power/Cooling

Unlike traditional data centers, in AI data centers:

  • GPU-based computing consumes enormous power and generates significant heat
  • High B/W networks consume additional power during massive data transfers between GPUs
  • Power systems (SMR/HVDC) must stably supply high power density
  • Liquid cooling (Liquid/CDU) must handle high-density GPU heat in real-time

These elements must be closely integrated in design, and optimizing just one element cannot guarantee overall system performance.

๐Ÿ’ก Key Message

AI workloads require moving beyond the traditional layer-by-layer independent design approach of conventional data centers, demanding that computing-network-power-cooling be designed as one integrated system. This demonstrates that a holistic approach is essential when building AI data centers.


๐Ÿ“ Summary

AI data centers fundamentally differ from traditional data centers through the tight integration of computing, networking, power, and cooling systems. GPU-based AI workloads create unprecedented power density and heat generation, requiring liquid cooling and HVDC power systems. Success in AI infrastructure demands holistic design where all components are co-optimized rather than independently engineered.

#AIDataCenter #DataCenterEvolution #GPUInfrastructure #LiquidCooling #AIComputing #LLM #DataCenterDesign #HighPerformanceComputing #AIInfrastructure #HVDC #HolisticDesign #CloudComputing #DataCenterCooling #AIWorkloads #FutureOfDataCenters

With Claude