Walking with
The Computing for the Fair Human Life.

This diagram illustrates the key differences between traditional programming methods and modern machine learning approaches. The analytical approach follows clearly defined rules designed by humans and can precisely explain results, while the empirical approach learns patterns from data and improves efficiency through parallel processing but leaves decision-making processes as a black box.
with claude

It’s in deep thought that growth begins—now, take action.

This image illustrates a crucial difference in predictability between single-factor and multi-factor systems.
In the Sequential (Serial) model:
In contrast, the Parallel model shows:
In our actual world, purely single-factor systems rarely exist. Even seemingly simple phenomena consist of interactions between various elements. Weather, economics, ecosystems, human health, social phenomena – all real systems comprise numerous variables and their complex interrelationships. This is why real-world phenomena exhibit probabilistic characteristics, which is not merely due to our lack of knowledge but an inherent property of complex systems.
With Claude
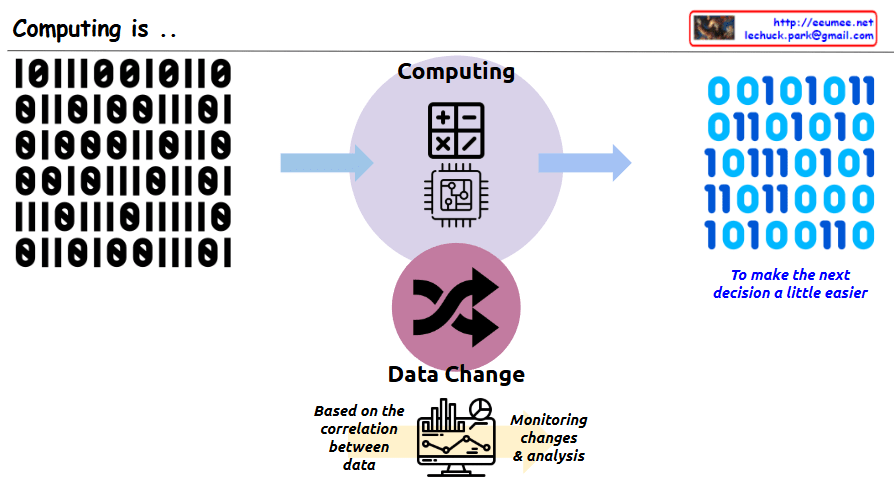
This image illustrates the core concept of “Computing.” The key message is that computing is a process of transforming data to make people’s next decisions easier.
In the center, there is a circle with the title “Computing” along with calculator and computer chip icons. On the left side, there is binary input data (0s and 1s), which is shown being transformed through the central computing process into different binary output on the right side. Next to the binary output on the right is blue italic text saying “To make the next decision a little easier,” emphasizing that the purpose of this data transformation is to aid human decision-making.
At the bottom of the image, there is a section titled “Data Change” with cycling arrows representing data transformation. Below that, there’s a monitor displaying charts and graphs with descriptions “Based on the correlation between data” and “Monitoring changes & analysis,” showing that analyzing relationships between data is important for supporting decision-making.
With Claude

This image presents a concept titled “Think by a Vector” that compares two approaches to handling data.
The image shows a data processing flow starting from what appears to be a network or system diagram on the left, which outputs binary data (represented as 0s and 1s) labeled as “Data Explosion.” This data can then be processed in two different ways:
The main message appears to be advocating for vector-based thinking or processing, which focuses on extracting and working with key features rather than processing every individual data point. This approach is presented as more efficient and effective than the raster-based approach.
With Claude