GPU vs NPU on Deep learning

This diagram illustrates the differences between GPU and NPU from a deep learning perspective:

GPU (Graphic Process Unit):

  • Originally developed for 3D game rendering
  • In deep learning, it’s utilized for parallel processing of vast amounts of data through complex calculations during the training process
  • Characterized by “More Computing = Bigger Memory = More Power,” requiring high computing power
  • Processes big data and vectorizes information using the “Everything to Vector” approach
  • Stores learning results in Vector Databases for future use

NPU (Neuron Process Unit):

  • Retrieves information from already trained Vector DBs or foundation models to generate answers to questions
  • This process is called “Inference”
  • While the training phase processes all data in parallel, the inference phase only searches/infers content related to specific questions to formulate answers
  • Performs parallel processing similar to how neurons function

In conclusion, GPUs are responsible for processing enormous amounts of data and storing learning results in vector form, while NPUs specialize in the inference process of generating actual answers to questions based on this stored information. This relationship can be summarized as “training creates and stores vast amounts of data, while inference utilizes this at the point of need.”

With Claude
Operation with LLM

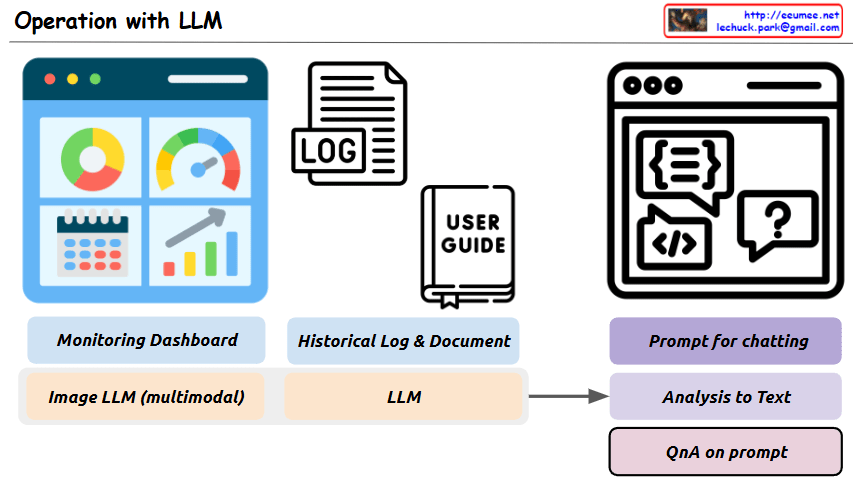
This image is a diagram titled “Operation with LLM,” showing a system architecture that integrates Large Language Models (LLMs) with existing operational technologies.

The main purpose of this system is to more efficiently analyze and solve various operational data and situations using LLMs.

Key components and functions:

  1. Top Left: “Monitoring Dashboard” – Provides an environment where LLMs can interpret image data collected from monitoring screens.
  2. Top Center: “Historical Log & Document” – LLMs analyze system log files and organize related processes from user manuals.
  3. Top Right: “Prompt for chatting” – An interface for interacting with LLMs through appropriate prompts.
  4. Bottom Left: “Image LLM (multimodal)” – Represents multimodal LLM functionality for interpreting images from monitoring screens.
  5. Bottom Center: “LLM” – The core language model component that processes text-based logs and documents.
  6. Bottom Right:
    • “Analysis to Text” – LLMs analyze various input sources and convert them to text
    • “QnA on prompt” – Users can ask questions about problem situations, and LLMs provide answers

This system aims to build an integrated operational environment where problems occurring in operational settings can be easily analyzed through LLM prompting and efficiently solved through a question-answer format.

With Claude

Add with power

Add with Power: 8-Bit Binary Addition and Energy Transformation

Core Mechanism:

  1. Input: Two 8-energy binary states (both rows ending with 1)
  2. Computation Process: 1+1 = 2 (binary overflow occurs)
  3. Result:
    • Output row’s last bit changed to 0
    • Part of energy converted to heat

Key Components:

  • Two input rows with 8 binary “energies”
  • Computing symbol (+) representing addition
  • A heat generation (?) box marked x8
  • Resulting output row with modified energy state

Fundamental Principle: “All energies must be maintained with continuous energies for no error (no changes without Computing)”

This diagram illustrates:

  • Binary addition process
  • Energy conservation and transformation
  • Information loss during computation
  • Relationship between computation, energy, and heat generation

The visual representation shows how a simple 8-bit addition triggers energy transfer, with overflow resulting in heat production and a modified binary state.

WIth Claude

Digital Twin and the LLM

Digital Twin Concept

A Digital Twin is composed of three key elements:

  • High Precision Data: Exact, structured numerical data
  • Real 3D Model: Visual representation that is easy to comprehend
  • History/Prediction Simulation: Temporal analysis capabilities

LLM Approach

Large Language Models expand on the Digital Twin concept with:

  • Enormous Unstructured Data: Ability to incorporate and process diverse, non-structured information
  • Text-based Interface: Making analysis more accessible through natural language rather than requiring visual interpretation
  • Enhanced Simulation: Improved predictive capabilities leveraging more comprehensive datasets

Key Advantages of LLM over Traditional Digital Twin

  1. Data Flexibility: LLMs can handle both structured and unstructured data, expanding beyond the limitations of traditional Digital Twins
  2. Accessibility: Text-based interfaces lower the barrier to understanding complex analyses
  3. Implementation Efficiency: Recent advances in LLM and GPU technologies make these solutions more practical to implement than complex Digital Twin systems
  4. Practical Application: LLMs offer a more approachable alternative while maintaining the core benefits of Digital Twin concepts

This comparison illustrates how LLMs can serve as an evolution of Digital Twin technology, providing similar benefits through more accessible means and potentially expanding capabilities through their ability to process diverse data types.

With Claude

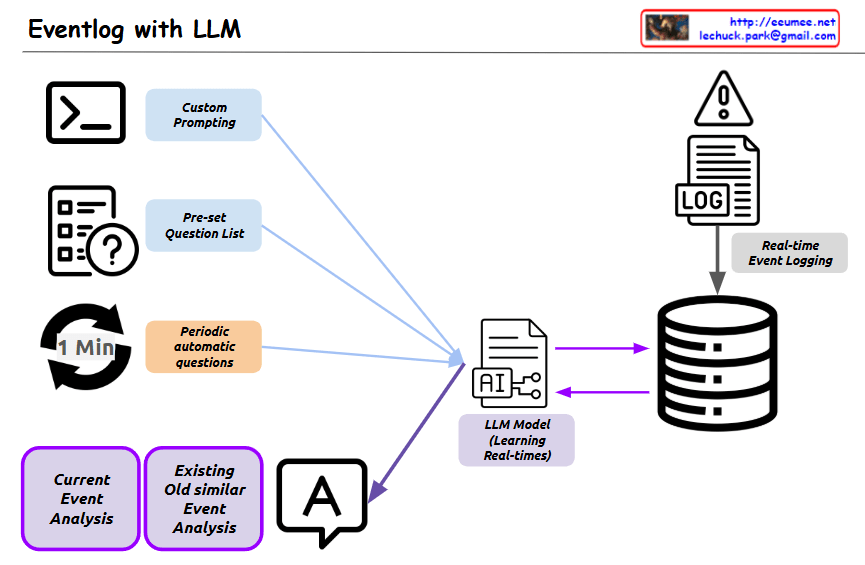
Eventlog with LLM

  1. Input methods (left side):
    • A command line/terminal icon with “Custom Prompting”
    • A questionnaire icon with “Pre-set Question List”
    • A timer icon (1 Min) with “Periodic automatic questions”
  2. Processing (center):
    • An “LLM Model” component labeled as “Learning Real-times”
    • Database/storage components for “Real-time Event Logging”
  3. Output/Analysis (bottom):
    • Two purple boxes for “Current Event Analysis” and “Existing Old similar Event Analysis”
    • A text/chat bubble showing output

This system collects and updates unstructured text-based event logs in real-time, which are then learned by the LLM. Through user-input questions, predefined question lists, or periodically auto-generated questions, the system analyzes current events and compares them with similar past cases to provide comprehensive analytical results.

The primary purpose of this system is to efficiently process large volumes of event logs from increasingly large and complex IT infrastructure or business systems. This helps operators easily identify important events, make quick judgments, and take appropriate actions. By leveraging the natural language processing capabilities of LLMs, the system transforms complex log data into meaningful insights, significantly simplifying system monitoring and troubleshooting processes.

With Claude

Reliability & Efficiency

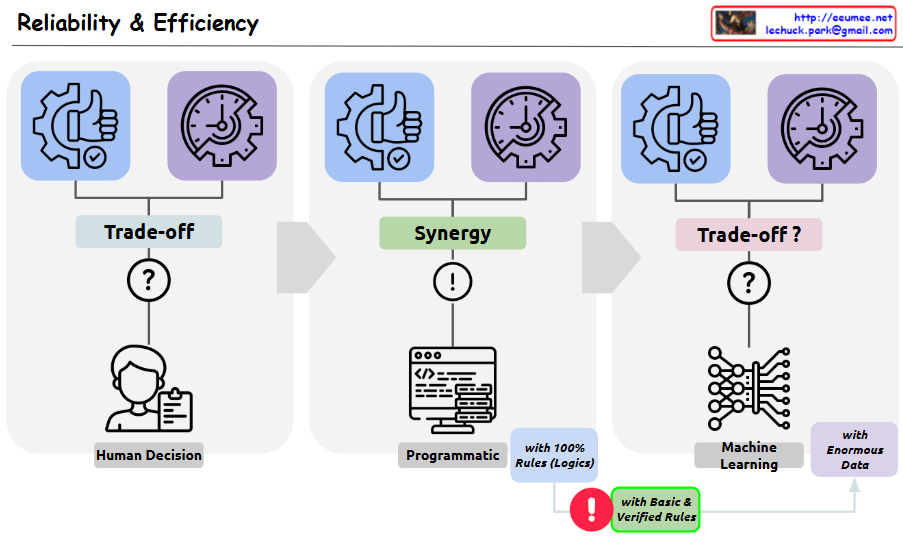
This image is a diagram showing the relationship between Reliability and Efficiency. Three different decision-making approaches are compared:

  1. First section – “Trade-off”:
    • Shows Human Decision making
    • Indicates there is a trade-off relationship between reliability and efficiency
    • Displays a question mark (?) symbol representing uncertainty
  2. Second section – “Synergy”:
    • Shows a Programmatic approach
    • Labeled as using “100% Rules (Logic)”
    • Indicates there is synergy between reliability and efficiency
    • Features an exclamation mark (!) symbol representing certainty
  3. Third section – “Trade-off?”:
    • Shows a Machine Learning approach
    • Labeled as using “Enormous Data”
    • Questions whether the relationship between reliability and efficiency is again a trade-off
    • Displays a question mark (?) symbol representing uncertainty

Importantly, the “Basic & Verified Rules” section at the bottom presents a solution to overcome the indeterminacy (probabilistic nature and resulting trade-offs) of machine learning. It emphasizes that the rules forming the foundation of machine learning systems should be simple and clearly verifiable. By applying these basic and verified rules, the uncertainty stemming from the probabilistic nature of machine learning can be reduced, suggesting an improved balance between reliability and efficiency.

with Claude

Human, Data,AI

The Key stages in human development:

  1. The Start (Humans)
  • Beginning of human civilization and knowledge accumulation
  • Formation of foundational civilizations
  • Human intellectual capacity and creativity as key drivers
  • The foundation for all future developments
  1. The History Log (Data)
  • Systematic storage and management of accumulated knowledge
  • Digitalization of information leading to quantitative and qualitative growth
  • Acceleration of knowledge sharing and dissemination
  • Bridge between human intelligence and artificial intelligence
  1. The Logic Calculation (AI)
  • Logical computation and processing based on accumulated data
  • New dimensions of data utilization through AI technology
  • Automated decision-making and problem-solving through machine learning and deep learning
  • Represents the current frontier of human technological achievement

What’s particularly noteworthy is the exponential growth curve shown in the graph. This exponential pattern indicates that each stage builds upon the achievements of the previous one, leading to accelerated development. The progression from human intellectual activity through data accumulation and management, ultimately leading to AI-driven innovation, shows a dramatic increase in the pace of advancement.

This developmental process is significant because:

  • Each stage is interconnected rather than independent
  • Previous stages form the foundation for subsequent developments
  • The rate of progress increases exponentially over time
  • Each phase represents a fundamental shift in how we process and utilize information

This timeline effectively illustrates how human civilization has evolved from basic knowledge creation to data management, and finally to AI-powered computation, with each stage marking a significant leap in our technological and intellectual capabilities.

With Claude